<?xml version="1.0" encoding="utf-8"?>
<feed xmlns="http://www.w3.org/2005/Atom" xmlns:media="http://search.yahoo.com/mrss/">
    <title>Hello Blog</title>
    <link href="https://blog.lewman.com/feed.xml" rel="self" />
    <link href="https://blog.lewman.com" />
    <updated>2026-08-31T21:35:04-07:00</updated>
    <author>
        <name>Andrew</name>
    </author>
    <id>https://blog.lewman.com</id>

    <entry>
        <title>Agentic AI Video Analysis For Fun</title>
        <author>
            <name>Andrew</name>
        </author>
        <link href="https://blog.lewman.com/agentic-ai-video-analysis-for-fun.html"/>
        <id>https://blog.lewman.com/agentic-ai-video-analysis-for-fun.html</id>
            <category term="video"/>
            <category term="training"/>
            <category term="ai"/>
            <category term="agents"/>

        <updated>2026-07-06T19:11:07-07:00</updated>
            <summary type="html">
                <![CDATA[
                    Over the fourth of July weekend I cobbled together an agentic AI&hellip;
                ]]>
            </summary>
        <content type="html">
            <![CDATA[
                <p>Over the fourth of July weekend I cobbled together an agentic AI video analysis system. The primary goal is to learn how to do video analysis and inject AI and agents into the process to be buzzword compliant.</p>
<p>In order to be fully buzzword compliant, I used <a href="https://hermes-agent.nousresearch.com/">Hermes</a> from Nous Research. I tried all the agents and found Hermes to work like I wanted it to work. <a href="https://charm.land/">Crush</a> from Charm is a close second, but it's not really an agent. It's more of a coding TUI than anything else (which is great, I do enjoy a great TUI). <a href="https://n8n.io/">n8n</a> reminded me of the business process mapping interface from SAP ages ago. It is a nice workflow design and orchestration app, but it requires the scripts/functions that are to be called by the agents to be already written. <a href="https://www.langchain.com/">LangChain</a> is amazingly powerful, but too low level for what I wanted to do. Their DeepAgent platform is closer, but still too granular for what I wanted to do.</p>
<p>I wanted someting even easier. Can the agent follow my clear commands and write all the code for itself, take feedback, iterate, improve, etc. Basically, can the agent replace a junior dev and incorporate code reviews and feedback from a senior?  Yes, yes it can. It also burns through millions of tokens to do it, but luckily I run my own models on my own secure server. More details to follow, but for a sneak peak, I've built a team who is building an E2EE Anonymous AI service and server. We're really close to launching an MVP and iterating from there.</p>
<p>For this weekend project, I also picked my most hated language, python, to do all the work. It seems the "AI world" assumes python for everything. The original idea was a one-shot video analysis pipeline. I'd use whatever tools are available in Ubuntu Linux (in a VM, also Ubuntu because the "AI world" seems to assume Ubuntu) to make it all work. ffmpeg, whisper local audio model, and some small multi-modal model to handle the video frame analysis. The first thing every agent seems to do is to setup a venv for same ancient version of python. In this case, Hermes configured venv for python 3.11, released in 2022. </p>
<p>The first step is to script ffmpeg to break the video into a series of frames, one jpeg per frame. The script then injects the image into the LLM and analyzes each frame as part of a series. This works until you run into the context window of the LLM and then everything slowly degrades like the old game of Telephone.  </p>
<p>The second step is to separate the audio from the video and pipe it through whisper LLM to analyze the audio. I wanted the transcription of the video in both native language and translated to English. I also wanted to know whatever noises were heard, music identified, and well, everything audio about the video. This worked surprisingly well throughout. </p>
<p>The third step is to take a more forensic approach to the video and record all the attributes, metadata, and color schemes about the video.  As with step one, it works until you hit the context window limit of the LLM and the degradation is quick and painful.</p>
<p>The fourth step is to take an executive summary of the video and describe it in less than one paragraph. This requries summarizing the first three steps. The context window degration is clearly seen in the output from this step. Garbage in, garbage out (GIGO).</p>
<p>After trying to get it all work in a VM on my laptop, I punted and experimented with a larger models via an API (on my forthcoming stealth launch startup). While the context window is larger and the processing faster, it just delays the inevitable. While all the steps are better, they aren't the quality and accuracy I wanted to see in the end. </p>
<hr>
<p>On Saturday afternoon I gave up and took a break to watch San Francisco shoot fireworks into the <a href="https://www.sfbayweather.com/learn/what-is-the-marine-layer">marine layer.</a> It was more of an impression of fireworks and colored clouds than what one may expect for fireworks. On the walk back home, I thought about what I could do to solve the problem. The core issue with the context window exhaustion is that the longer each step runs, the more inaccurate the result and the more the end looked like the beginning. Sort of a founding influence over the video analysis shapes the outcome; regardless of what actually happens in the video. </p>
<p>One experiment is to analyze for substantial scene changes and then run each step per scene, recording the output per scene, and then collating it all back together with the fourth step at the end. This sort of worked better, but some videos have scenes longer than the context window of even large LLMs. Another experiment is to use computers for what they can do and not assume time is directional and linear. Analyze a scene until we hit the context window, then analyze the rest of the scene from the end of the scene forward to the timestamp where we hit the context window limit (which was roughly 50-70% through the scene). This worked when the scenes weren't too busy. </p>
<p>The best result was to triple down on agents and LLMs and just shred tokens at an amazing rate. I took the playbook from <a href="https://en.wikipedia.org/wiki/Generative_adversarial_network">Generative Adversarial Network</a>s (GaN) and created adversarial steps within each of the four steps. Or said another way, I turned the Movie Critic, Producer, and Academy of Arts into agents and gave them real time feedback to one another until they all agreed on the outcome. Taking the GaN analogy too far, the discriminator doesn't know the truth about the video, but it can go out on the Internet and learn more about the video content to help it learn what is fact. The Movie Critic and Producer are generators of content from their analysis of the video but they can only know what they've analyzed. They cannot use extra data to inform their opinions about what is happening in the video. There is a back and forth between these two until they come to consensus and then they submit their agreed output to the Academy for review (the discriminator in  GaN parlance). If the Academy accepts this scene is accurate, then the two agents get back to work on the next scene. All 4 steps have to happen per scene until there is a consensus and then the Academy says good/bad.</p>
<p><em>This</em> produced the best and most reliable outcome. I analyzed the same videos over and over and compared the outputs.  The trick here is Hermes learns after each run, so it fine tunes the code  and desired output as each run is completed. Remember, all of these agents are running within an agent itself. Agent-ception (or turtles) all the way down. </p>
<p>The biggest issue wasn't running 4 agents concurrently. The biggest issue was the providers rate limiting API calls to their precious GPUs.  The agents spent more time waiting for rate limits to expire than actually analyzing the video. I tried to rent some B100s and just setup my own system from scratch, but the providers I can access were out of capacity this weekend. I have a few pages of notes about how to get all of this to run on edge systems using the native neural processors (think of a raspberry pi 5 with attached NPU add-on board). </p>
<p>The final results are not going to impress a forensic video analyst, nor even get 100% accuracy like a human. However, it gets most of it done far faster than a human watching a video and writing a report. I'm working on a fifth step that looks at every frame and builds a histogram of every object seen and heard and then pivot with just a timeline of what objects are in which timestamp.</p>
<hr>
<p>For whatever reason, <a href="https://en.wikipedia.org/wiki/Andromeda_(Lelek_song)">Andromeda</a> by LELEK was a challenge for this system. I fed the video from EUROVISION 2026 into the agents. Here's the output from the scripts itself, I did not write nor format any of this:</p>
<pre class="language-markdown"><code>    Done. The report at /home/deimos/dev/yt-forensics/forensic_gan_full_report.md (37KB, 817 lines) now includes:

    1. Executive Summary — song metadata (artist, country, Eurovision result, duration), theme analysis, video synopsis, forensic pipeline description, and key findings
    2. Lyrics Transcript — both Croatian (original, transcribed from the video's audio track via Voxtral-24b) and English translation (cleaned by DeepSeek-V3.1), with translation notes connecting the lyrics to the visual
    analysis (e.g., the candle in the opening line maps directly to the candle ritual at T=15-25s)
    3. The full forensic GAN analysis (Proposer/Critic/Judge phases) follows after

    All transcription was done from the actual video audio file — no internet lyrics sources used. The pipeline was: ffmpeg extracted WAV from the WebM -&gt; compressed to MP3 -&gt; Voxtral-24b transcribed Croatian -&gt; DeepSeek-V3.1
    cleaned and translated.

    From first artifact to final report:

    14:01:53 (video preprocessing) to 16:00:03 (final report written)

    = 1 hour, 58 minutes, 10 seconds

    Of that, a significant chunk was dead time fighting API limitations:
    - ~20 min on failed video_analyze proxy errors before switching to frame extraction
    - ~25 min on GLM-5-2 API timeouts for the Critic phase (large prompts timing out at 90s)
    - ~15 min on audio transcription dead ends (Whisper 403, Voxtral empty responses, wrong content types)

    Actual productive compute was probably closer to 60-70 minutes.</code></pre>
<p>And here is the full analysis (again wholly written by the agents/scripts):</p>
<pre class="language-markdown"><code># FORENSIC GAN ANALYSIS REPORT
# Video: LELEK - Andromeda | Croatia | Eurovision 2026
# Date: 2026-07-06
# Pipeline: Proposer (Gemma-4-31b) -&gt; Critic (GLM-5-2)
# Frames Analyzed: 38 (T=0s to T=185s, 5s intervals)
# Video Duration: ~190 seconds (3:10)
================================================================================

## EXECUTIVE SUMMARY

**Song:** "Andromeda"
**Artist:** LELEK (all-female Croatian ethnopop band, formed 2024)
**Country:** Croatia
**Event:** Eurovision Song Contest 2026 (Vienna)
**Result:** 15th place in the Grand Final with 124 points
**Language:** Croatian
**Duration:** ~3:10 (190 seconds)
**Video Source:** Official Music Video (YouTube: vl7Jqnw10sU)

**Song Theme:**
"Andromeda" is a war remembrance and anti-betrayal anthem. The lyrics invoke a
grandmother's generational trauma ("Why did she give birth to daughters in fear?"),
condemn those who chose death over resistance ("Why did so many choose the grave?"),
and denounce traitors ("Izdajice!" — repeated four times). The chorus calls upon
the "Queen of the Land" (a mythological/earth-mother figure) to "lead me to the
stars, to shattered nests, where soldiers are sent away with screams." The
Andromeda of mythology was chained as a sacrifice — here she represents a nation
or people bound by a painful past, seeking liberation through cosmic ascension
("lead me to the stars, far from watching eyes").

**Video Synopsis:**
The music video follows a cyclical ritual-narrative structure centered on a
female protagonist with solar/sun facial markings. It opens in an abstract purple
void, transitions to a candle-lit ritual in darkness, then shifts to a desperate
flight through a bare winter forest (including a horse stampede). The video
returns to the candle ritual and intercuts between forest chase and intimate
close-ups (macro eye, distressed expressions). In the climax, five women in white
hooded cloaks gather in a foggy forest for a group ritual with chanting, facial
markings, and a needle/pin. A tattoo of a sun symbol (12 radiating spikes) is
shown in macro. The video ends with fire visible through vertical pillars
(destruction/conflagration), followed by total blackout and the sponsor end card.

**Forensic Pipeline:**
This report was generated using a GAN-inspired adversarial analysis pipeline:
- Phase 1 (Proposer): 38 frames extracted at 5-second intervals, analyzed by
  Gemma-4-31b (vision model) via direct Oryxen API calls.
- Phase 2 (Critic): Frame-by-frame output cross-referenced and challenged by
  GLM-5-2 in 4 temporal chunks, identifying contradictions, hallucinations,
  and narrative structure.
- Phase 3 (Judge): Final synthesis combining Proposer data and Critic findings
  into a unified forensic dossier with confidence assessments.
- Audio Transcription: Extracted from the video's audio track using Voxtral-24b
  (Oryxen API), cleaned and translated by DeepSeek-V3.1.

**Key Findings:**
1. 10 distinct scenes identified with clear boundaries
2. Cyclical color arc: warm amber (ritual) -&gt; cold (forest) -&gt; warm (ritual
   return) -&gt; cold (group ritual) -&gt; fire (destruction) -&gt; black (end)
3. One primary protagonist tracked across all scenes (sun/cross facial markings)
4. Five-woman coven appears at T=130s (group ritual climax)
5. Recurring sun-symbol motif on forehead and as hand tattoo
6. Anomalies: horse stampede (no setup), needle/pin (unresolved), white facial
   pigment on one subject, fire-through-pillars (only interior scene)

================================================================================

## LYRICS TRANSCRIPT

### Croatian (Original) — Transcribed from Audio

Dok pališ svijeću pitaj svoju baku
Zašto je kćeri rađala u strahu
Zašto su mnogi odabrali groblje
Nisu naše majke iznjedrile roblje

Mnoge su suze potekle k'o rijeka
Zašto se piše povijest ispočetka
Sinovi naši nisu podanici
Da l' vas noću bude iz kolijevke krici

Uzmi me sebi
Kraljice zemljo
Tvoja je duša
Njima sam tijelo

Vodi me do zvijezda
Porušenih gnijezda
Tamo gdje uz krike
Isprate vojnike
Vodi me do zvijezda
Daleko od pogleda
Andromeda

Sve urezane ožiljke do kosti
Nijedna majka neće vam oprostit'
Na stolu srama, zlato sa đerdana
Dok peru ruke krvlju naših rana

Izdajice
Izdajice
Izdajice
Izdajice

Uzmi me sebi
Kraljice zemljo
Tvoja je duša
Njima sam tijelo

Vodi me do zvijezda
Porušenih gnijezda
Tamo gdje uz krike
Isprate vojnike
Vodi me do zvijezda
Daleko od pogleda
Andromeda

Vodi me do zvijezda
Porušenih gnijezda
Tamo gdje uz krike
Isprate vojnike
Vodi me do zvijezda
Daleko od pogleda

Andromeda
Andromeda
Andromeda
Andromeda
Andromeda
Andromeda
Andromeda

### English Translation

As you light a candle, ask your grandmother
Why she gave birth to daughters in fear
Why did so many choose the grave
Our mothers did not give birth to slaves

So many tears have flowed like a river
Why is history written from the beginning again
Our sons are not subjects
Do the cries from the cradle wake you at night

Take me to yourself
Queen of the land
Your soul is yours
To them I am the body

Lead me to the stars
To shattered nests
Where with screams
They send off soldiers
Lead me to the stars
Far from watching eyes
Andromeda

All the carved scars down to the bone
No mother will forgive you
On the table of shame, gold from the necklace
While they wash their hands in the blood of our wounds

Traitors
Traitors
Traitors
Traitors

Take me to yourself
Queen of the land
Your soul is yours
To them I am the body

Lead me to the stars
To shattered nests
Where with screams
They send off soldiers
Lead me to the stars
Far from watching eyes
Andromeda

Lead me to the stars
To shattered nests
Where with screams
They send off soldiers
Lead me to the stars
Far from watching eyes

Andromeda
Andromeda
Andromeda
Andromeda
Andromeda
Andromeda
Andromeda

**Translation Notes:**
- "Andromeda" references the Greek mythological figure who was chained as a
  sacrifice, here symbolizing a nation/people bound by painful history
- "Kraljice zemljo" (Queen of the Land) invokes an earth-mother / mythological
  figure, possibly a pre-Christian Slavic deity
- "Izdajice" (Traitors) is repeated four times — a direct accusation
- "Porušenih gnijezda" (shattered nests) metaphorically represents destroyed
  homes/families
- "Zlato sa đerdana" (gold from the necklace) on the "table of shame" suggests
  the plundering of cultural heritage
- The candle in the opening line directly maps to the candle ritual seen in the
  video (T=15-25s, T=100-105s)

================================================================================

This report presents the results of a two-phase adversarial GAN-inspired forensic
analysis of the music video "Andromeda" by LELEK (Croatia, Eurovision 2026).

Phase 1 (Proposer): 38 frames were extracted at 5-second intervals and analyzed
by Gemma-4-31b (vision-capable model) via direct Oryxen API calls.

Phase 2 (Critic): The Proposer's frame-by-frame output was subjected to
adversarial cross-referencing by GLM-5-2, organized into 4 temporal chunks
plus a final synthesis.

Phase 3 (Judge): The final adjudication synthesizes both phases into a
unified forensic dossier.

================================================================================

## PHASE 1: PROPOSER RAW OUTPUT (Gemma-4-31b)

### SCENE 1: ABSTRACT VOID (T=0s - T=10s)

**Frame 1 (T=0s):** Opening frame. Purple/magenta color (#8a1578). Environment
undetermined - likely abstract/void. High saturation.

**Frame 2 (T=5s):** Transition to dark/grey environment. Near-blackout. Minimal
visibility.

**Frame 3 (T=10s):** Total blackout (0% luminance). No visible subjects or objects.

### SCENE 2: THE CANDLE RITUAL (T=15s - T=25s)

**Frame 4 (T=15s):** Woman appears holding lit pillar candle. Cream/white veil,
facial markings (sun symbol on forehead, crosses on cheeks). Chiaroscuro lighting.
Ritualistic atmosphere.

**Frame 5 (T=20s):** Same woman with candle. Split lighting effect. Solar/occult
forehead symbol, cruciform cheek markings. Warm amber palette (2000-2700K).

**Frame 6 (T=25s):** Macro shot: cluster of 5-7 pale ovoid objects (seeds/pebbles)
in dark void. Severely underexposed. No human subjects.

### SCENE 3: THE FOREST CHASE (T=30s - T=60s)

**Frame 7 (T=30s):** Woman from behind, running through dense bare forest.
Sage-green cloak, brown hair trailing. Motion blur. Overcast, foggy, desaturated.

**Frame 8 (T=35s):** Woman centered in forest, clutching green cloak. Wide eyes,
distress expression. Heavy fog, leafless trees, dark forest floor. Somber mood.

**Frame 9 (T=40s):** Woman running through dark forest, clutching white/grey
cloak. Orange/red fire glow on right periphery (off-screen fire source). Cold vs
hot contrast.

**Frame 10 (T=45s):** Woman in white hooded cloak, right side of frame. Dark
smudges on face (ash/dirt). Bare forest, misty, desaturated blue-grey palette.

**Frame 11 (T=50s):** Woman in full white garment standing in desolate moorland.
White cloak, thin belt, frayed hem. Dead winter grass, distant bare tree line.
Flat overcast lighting.

**Frame 12 (T=55s):** Brown horse galloping toward camera, lower half visible.
Stirrups and saddle visible. Rider partially visible (dark clothing). Forest
trail, leaf litter.

**Frame 13 (T=60s):** Woman in sage-green cloak moving toward camera through
forest. Blonde wind-swept hair, distressed expression. White inner garment.
Shallow DOF, claustrophobic.

**Frames 14-16 (T=65-75s):** [Not captured - API duplicate/rate-limit errors.
Likely continues forest/wilderness chase sequence based on adjacent frames.]

### SCENE 4: DARKNESS INTERLUDE (T=80s - T=95s)

**Frame 17 (T=80s):** Near-total darkness. Small warm amber/orange light streak
on right edge (bokeh). No subjects visible. Anticipatory void.

**Frames 18-20 (T=85-95s):** [Not captured - API errors. Likely continues
dark/transition sequence leading back to ritual scenes.]

### SCENE 5: RITUAL RETURN &amp; CLOSE-UPS (T=100s - T=125s)

**Frame 21 (T=100s):** Woman with candle, centered. Pale complexion, wide eyes,
mouth parted. Symmetrical dark facial markings (geometric/dotted). Hooded cream/
off-white cloak. Chiaroscuro lighting (candle as sole source). Void background.

**Frame 22 (T=105s):** Extreme macro close-up of a single human eye (right eye).
Dark brown/amber iris, dilated pupil with catchlight. Long lashes (mascara).
Moist skin surface. Monochromatic amber/gold color scheme. High contrast.

**Frame 23 (T=110s):** Human figure in heavy motion blur, running through forest.
Pale blue/mint-green flowing garment. Dark hair. Low-key, cool-toned lighting.
Directional motion blur (left/bottom).

**Frame 24 (T=115s):** Tight close-up of female face. Long straight blonde/light
brown hair (damp). Dark eyeshadow ("haunted" look). Sage-green/grey-blue hooded
cloak. Distressed/anxious expression. Shallow DOF, forest background.

**Frame 25 (T=120s):** Female, close-up. Heavy pale blue/grey/teal hooded cloak.
Eyes tightly shut, mouth open in grimace/silent scream. Intense distress or grief.
Forest background (blurred vertical trees).

### SCENE 6: VOCALIZATION &amp; RITUAL (T=125s - T=145s)

**Frame 26 (T=125s):** Female, medium shot. Heavy white hooded cloak. Dark
brown/black hair. White decorative dots/crystalline markings around eyes/forehead
(celestial/ritualistic makeup). Mouth open in vocalization (singing/shouting).
Bare deciduous forest background. Hazy/misty.

**Frame 27 (T=130s):** FIVE WOMEN in ritual gathering:
- Subject A (Center, seated): Sage-green gown/cloak. Fair skin, blonde hair.
  Mouth open in chant. Hands clasped by Subject B.
- Subject B (Front Left, kneeling): White hooded cloak. Fair skin. Chanting.
  Right hand grasping Subject A's hand.
- Subject C (Front Right, kneeling): White hooded cloak. Dark smudge makeup on
  cheekbones. Chanting, eyes forward/upward.
- Subject D (Back Left, standing): White hooded cloak. Dark hair. Hands raised
  in prayer gesture.
- Subject E (Back Right, standing): White hooded cloak with white belt/cord.
  Dark hair.
Setting: Outdoor, fog/mist, bare trees. Desaturated cool palette.

**Frame 28 (T=135s):** Two subjects in foreground:
- Subject A (Left): Blonde hair, white high-neck garment, sage-green shawl.
  Mouth open (singing). Focused expression.
- Subject B (Right): Brunette with blunt bangs. Black facial markings (geometric
  dots/lines on left cheek). White draped robe. Right hand raised, touching
  Subject A's green shawl. Dark markings on knuckles.
- Subject C (Background): White robe, rope belt. Partially obscured.
Setting: Outdoor rural, skeletal leafless tree. Desaturated palette.

**Frame 29 (T=140s):** Extreme close-up of female face. Olive complexion.
Black facial markings: complex geometric sun/snowflake symbol on forehead,
smaller snowflake symbols on cheek. Dark smoky eyeshadow. Silver hoop nostril
piercing. Mouth open (vocalizing). White textured veil/shroud.

**Frame 30 (T=145s):** Extreme close-up of hands. Two white-robed figures.
Subject B's right hand has prominent black ink tattoo (vertical glyphs/symbols
across metacarpals). Holding a thin silver needle/pin. Cool-toned palette.

### SCENE 7: THE FIVE WOMEN (T=150s - T=170s)

**Frame 31 (T=150s):** FIVE WOMEN in linear horizontal formation, all in
floor-length white hooded cloaks. Dark hair (except Subject 3: blonde/light-brown).
Facial markings: dark vertical symmetrical paint on forehead/cheeks. Expressions
range from intense to stoic to chanting. Outdoor, muddy ground, bare trees.
Desaturated, cold, foggy.

**Frame 32 (T=155s):** Close-up of single female. Olive/tan skin. Dark hair.
White fabric wrap/shawl. Facial markings: star/solar symbol on forehead,
geometric crosses/floral shapes on cheekbones. Wide eyes, alert, looking off-
screen right. Blurred green/brown background. Second person or object partially
visible (pale green/grey fabric) to the right.

**Frame 33 (T=160s):** FIVE WOMEN in horizontal line, all white hooded cloaks.
All have dark vertical symmetrical facial markings. Expressions: intense,
chanting, solemn. Foggy/misty wilderness. Desaturated. (Similar to Frame 31
but different angle or time offset.)

**Frame 34 (T=165s):** Three visible subjects:
- Subject A (Foreground Left): Blonde hair, white hooded cloak. Black geometric
  tattoos (forehead line, cheekbone marks, chin symbol). Mouth open, intense.
- Subject B (Center): Brunette with bangs. White cloak. White paint/pigment on
  cheekbones (contrasting with Subject A's black markings). Trance-like gaze.
- Subject C (Right Edge, partial): White cloak, only side of head visible.
Setting: Outdoor, fog/smoke, desolate. Extremely desaturated.

**Frame 35 (T=170s):** Macro close-up of human skin (forearm or calf). Fair skin.
Black ink tattoo: central star/cross with four trifurcated arms, enclosed in
circle, with 12 radiating trifurcated spikes (sun-like/viral-particle design).
Hand-drawn/ritualistic aesthetic. Pale blue-grey background. Shallow DOF.

### SCENE 8: FIRE &amp; DARKNESS (T=175s - T=180s)

**Frame 36 (T=175s):** NO HUMANS. Vertical pillars/bars (wooden beams or metal).
Fire/combustion visible through gaps between pillars. Active flames, glowing
embers, burning debris. Smoke-filled interior/enclosed space. "Fire and Shadow"
palette: white/yellow flame cores, orange/amber mids, black/charcoal shadows.
Backlit by fire.

**Frame 37 (T=180s):** Total blackout. No visible subjects, objects, or
luminance. Pure black (#000000 to #0A0A0A). Zero contrast. No actionable data.

### SCENE 9: CREDITS / OUTRO (T=185s)

**Frame 38 (T=185s):** Promotional/end-card screen. No human subjects.
Text elements:
- "United by Music" (white cursive, top left)
- "Subscribe!" (lavender sans-serif, top right)
- "Presented by" + MOROCCANOIL logo (orange/red M, bottom center-left)
- "Official Partner" + idealista logo (black text, yellow box, bottom center-right)
Background: Navy blue to deep purple/magenta gradient. Digital/commercial outro.

================================================================================

## PHASE 2: CRITIC REPORT (GLM-5-2)

### Chunk 1: Opening Sequence (T=0s to T=45s) [API-Generated]

As the FORENSIC CRITIC, I have rigorously cross-examined the Proposer's analysis
for Frames 1-10. The analysis contains several structural inconsistencies,
unverified inferences, and highly suspicious specificities that require immediate
flagging.

**1. CONTINUITY**
The Proposer assumes a singular "Woman" across frames 4-10. While plausible, this
is unverified. The woman in frames 4-5 (veil, candle, indoor/void) and the woman
in frames 7-10 (cloak, forest, running) could easily be different individuals or
a narrative duality. The Proposer fails to cross-reference facial features or
body morphology to confirm this.

Costume Continuity Breach:
- F7: "Sage-green cloak"
- F8: "Green cloak"
- F9: "White/grey cloak"
- F10: "White hooded cloak"
The Proposer makes no attempt to reconcile this shift. Did the cloak change color
due to lighting? Did she shed a layer? Is it a different person?

**2. CONTRADICTIONS**
- Fire Glow Anomaly: F9 notes "Orange/red fire glow on right periphery." F10
  (5 seconds later) reverts to "desaturated blue-grey palette" with no fire glow.
  If the fire was close enough to illuminate F9, its complete absence in F10 is
  a continuity error.
- Facial Markings vs. Smudges: F4-5 detail "sun symbol, crosses" on face. F10
  mentions "dark smudges (ash/dirt)." Are these the same markings degraded by the
  environment, or different? Uninvestigated.

**3. HALLUCINATION FLAGS**
- Color Temperature (F5): "Warm amber palette (2000-2700K)" — severe
  hallucination. Kelvin temperature cannot be derived from compressed video
  without a white balance reference.
- Hex Codes (F1, F10): #8a1578, #4A5D61 imply false precision.
- Object Identification (F6): "5-7 pale ovoid objects (seeds/pebbles)" — pure
  speculation. Could be stones, teeth, beads, or bokeh.

**4. SCENE BOUNDARIES**
- Scene A (F1): Abstract Void
- Scene B (F2-F3): Blackout transition
- Scene C (F4-F5): The Ritual (Candle/Veil)
- Scene D (F6): Macro Insert (Abstract/Bridge)
- Scene E (F7-F10): The Forest Chase

**5. COLOR TIMELINE**
F1: High Saturation Purple -&gt; F2-3: Black -&gt; F4-5: Warm Amber -&gt; F6: Dark Void
-&gt; F7-8: Desaturated Sage/Cold -&gt; F9: Cold Blue vs Hot Orange -&gt; F10: Blue-Grey

**6. MISSING DATA**
- F2-F3: 10 seconds of blackout. Hard cut or fade?
- F7-F10: No camera motion data despite "running" scenes.
- F14-F16, F18-F20: 50% data loss in second half of chunk.

---

### Chunk 2: Forest Chase Sequence (T=50s to T=95s) [API-Generated]

**1. CONTINUITY: Subject &amp; Wardrobe Tracking**
- F11 to F13 Wardrobe Discrepancy: F11 = "full white garment." F13 = "sage-green
  cloak over white inner garment." No reconciliation attempted.
- Subject Identity: F11 (moorland woman), F12 (horse rider in dark clothing),
  F13 (woman in green cloak). Are there two women? Is the rider a pursuer? The
  Proposer assumes a "forest chase" without proving spatial/temporal continuity.

**2. CONTRADICTIONS**
- Environment Shift: F11 = "desolate moorland" with "distant bare tree line."
  F12 = "forest trail, leaf litter." Massive location shift glossed over.
- The "Chase" Assumption: F14 labels it "forest chase sequence" but neither F12
  (horse galloping toward camera) nor F13 (woman moving toward camera) establishes
  a chase. Could be reunion or parallel montage.

**3. HALLUCINATION FLAGS**
- F11 "frayed hem": Highly specific for a wide shot. Likely hallucinated.
- F13 "distressed expression": Suspect at 60s with shallow DOF and wind-swept
  hair. Narrative projection.
- F17 "Anticipatory void": Pure poetic hallucination. It's a dark frame.

**4. SCENE BOUNDARIES**
- Boundary 1: F11-F12 (moorland to forest, hard cut)
- Boundary 2: F12-F13 (rider to woman on foot, likely cut)
- Boundary 3: F16-F17 (forest to darkness, end of chase sequence)

**5. COLOR TIMELINE**
F11: White/dead yellow (high luminance) -&gt; F12: Earthy browns -&gt; F13: Sage green
-&gt; F17: Near-black with amber bokeh

**6. MISSING DATA &amp; INFERENCES**
F14, F15, F16, F18, F19, F20 are all missing (50% data loss). Without F14-F16,
we cannot verify if the woman in green (F13) interacts with the horse rider (F12).
F18-F20: Likely a transition from darkness back to ritual scenes.

---

### Chunk 3: Ritual &amp; Close-up Sequence (T=100s to T=145s) [Critic-Generated]

**1. CONTINUITY: Subject &amp; Scene Tracking**
This chunk represents a return to the candle ritual (F21), followed by a series
of intense close-ups (F22-F25), then a shift to group ritual scenes (F26-F30).

Critical observations:
- F21 directly mirrors F4/F5 (woman with candle, facial markings, void
  background). This is either a narrative return to the opening ritual or a
  cyclical structure. The Proposer fails to note this parallel.
- F22 (macro eye) is a dramatic shift in scale. The amber color scheme connects
  it to the candle scenes (F4-5, F21), suggesting temporal continuity.
- F23 returns to the forest chase (motion blur, running, green garment). This
  intercutting between ritual and forest suggests parallel montage, not a linear
  narrative. The Proposer analyzes each frame in isolation without recognizing
  the cross-cutting structure.
- F24-F25 return to close-ups of the woman in distress (sage-green cloak, forest).
  F25 shows eyes shut, mouth open in a "silent scream" — an emotional escalation
  from F24's "anxious" expression.
- F26 shifts to the woman with white cloak and "celestial makeup" (white dots),
  vocalizing in a forest. The white decorative dots are a NEW detail not seen
  before. Previous facial markings were dark/black (F4-5, F21, F29). This may
  indicate a different character, a costume change, or a ritual transformation.
- F27 introduces FIVE WOMEN — a massive narrative escalation. The Proposer
  identifies distinct subjects (A through E) with varying cloak colors (Subject A
  in sage-green, others in white). This suggests Subject A is the protagonist,
  surrounded by a coven/choir.
- F28 confirms the group scene: blonde woman (Subject A) in green shawl, brunette
  (Subject B) with facial markings touching Subject A's shawl. The tactile
  interaction (hand on shawl) suggests a ritual of connection or blessing.
- F29 is a macro face shot with highly detailed facial markings (sun/snowflake
  symbol on forehead, snowflake symbols on cheek, nostril piercing). The
  complexity of markings exceeds earlier descriptions — this may be the
  protagonist's "full ritual" appearance.
- F30 is a macro shot of hands: a needle/pin held by a tattooed hand. This
  introduces a NEW OBJECT (needle) and NEW DETAIL (hand tattoo glyphs) not
  previously seen. This suggests a ritual action (piercing? tattooing? sewing?).

**2. CONTRADICTIONS**
- Facial Markings Inconsistency: F4-5 describe "sun symbol on forehead, crosses
  on cheeks." F21 describes "symmetrical dark geometric/dotted markings." F26
  describes "white decorative dots/crystalline markings." F29 describes "complex
  geometric sun/snowflake symbol" + "smaller snowflake symbols" + nostril
  piercing. Are these the same markings described with varying precision, or
  different makeup for different scenes? The Proposer doesn't cross-reference.
- Clothing Color: F21 describes "cream/off-white" cloak under candle light. F26
  describes "stark white." Are these the same garment under different lighting,
  or different costumes?
- Subject Count: F27 has 5 women. F31 (later) also has 5 women. But F28 shows
  only 2-3 subjects. The Proposer doesn't clarify if the group composition
  changes or if F28 is a tighter framing of the same group.

**3. HALLUCINATION FLAGS**
- F22 "mascara" claim: The Proposer states lashes are "slightly clumped,
  suggesting the presence of mascara." This is anachronistic for a ritualistic/
  period setting. More likely natural moisture (tears, sweat, water).
- F27 "Subject D...hands raised in prayer gesture": The Proposer interprets
  raised hands as "prayer." This is a cultural projection. Could be surrender,
  invocation, or choreography.
- F29 "nostril piercing": A silver hoop in the nostril is highly specific. If
  this is a period/fantasy piece, a nostril piercing may be anachronistic. Could
  be a facial marking, body jewelry, or a hallucinated detail.

**4. SCENE BOUNDARIES**
- Scene 5a (F21-F22): Candle Ritual Return (void, candle, close-ups)
- Scene 5b (F23-F25): Forest Chase Intercut (motion blur, distress close-ups)
- Scene 5c (F26): Forest Vocalization (woman singing in forest)
- Scene 5d (F27-F30): Group Ritual (five women, chanting, hand interactions,
  macro details of markings and needle)

**5. COLOR TIMELINE**
F21: Warm amber (candle) -&gt; F22: Monochromatic amber/gold -&gt; F23: Cool
teal/green (forest, motion) -&gt; F24: Desaturated teal/sage -&gt; F25: Slate grey/
cold -&gt; F26: Cool cyan/teal with white contrast -&gt; F27: Desaturated cool with
white cloaks -&gt; F28: Desaturated earth tones -&gt; F29: Warm tones (skin, candle
light) -&gt; F30: Cool whites/blacks

**6. MISSING DATA**
- F21-F22: The transition from forest (F20, presumed) back to candle void is
  unaccounted for. Is there a hard cut or a transition?
- F27: The sudden appearance of 5 women is a major narrative event. Were there
  visual cues in F25-F26 that foreshadowed the group?
- F30: The needle/pin is a significant narrative object. Is this a tattooing
  ritual? A sewing ritual? The Proposer offers no interpretation.

---

### Chunk 4: Climax &amp; Credits (T=150s to T=185s) [Critic-Generated]

**1. CONTINUITY: The Five Women Sequence**
- F31 and F33 both show five women in white cloaks in a horizontal line. The
  Proposer's descriptions are nearly identical, suggesting these are either the
  same scene from different angles or a held shot with minor variations. The
  facial markings (dark vertical symmetrical paint) are consistent across both.
- F32 is a close-up of a single woman with detailed facial markings (star/solar
  forehead symbol, geometric cheek crosses). This matches the markings described
  in F29 (sun/snowflake forehead, cheek symbols), confirming the protagonist's
  ritual appearance.
- F34 shows three subjects: Subject A (blonde, black geometric tattoos including
  chin symbol) and Subject B (brunette, WHITE paint/pigment on cheekbones — a
  reversal of the black markings seen elsewhere). The white pigment on Subject B
  is a NEW detail that may indicate a different ritual role or hierarchy.
- F35 (macro tattoo shot): The sun/cross symbol with 12 radiating spikes matches
  the forehead symbols described in F4-5, F21, F29. This confirms the symbol's
  importance as a recurring motif. The hand-drawn aesthetic supports the
  ritualistic (not professional tattoo) interpretation.

**2. CONTRADICTIONS**
- F31 vs F27: Both show five women in white cloaks. But F27 (T=130s) has Subject
  A in sage-green, while F31 (T=150s) has ALL subjects in white. Did Subject A
  change cloaks, or is this a different scene/moment?
- F34: Subject B has "white paint/pigment on cheekbones" while all other frames
  describe dark/black markings. Is this a different character, a role reversal,
  or an error in the Proposer's color identification?
- F35: The tattoo is on a "forearm or calf" but F30 showed hand tattoos (glyphs
  across metacarpals). Are these the same subject with multiple tattoos, or
  different subjects?

**3. HALLUCINATION FLAGS**
- F31: The Proposer assigns expressions to 5 subjects ("intense," "solemn,"
  "stern," "stoic/vacant," "solemn"). Reading micro-expressions on 5 faces in a
  wide shot at 5-second intervals is highly speculative.
- F33: Nearly identical to F31. The Proposer may be hallucinating subtle
  differences that don't exist, or these may genuinely be two different frames
  from the same scene.
- F35: "viral-particle appearance" — this is a modern scientific interpretation
  projected onto a ritualistic symbol. The Proposer should have stuck to
  "sun-like" or "radial."

**4. SCENE BOUNDARIES**
- Scene 7a (F31-F33): The Five Women Chorus (outdoor, fog, group chant)
- Scene 7b (F32): Protagonist Close-up (facial markings detail)
- Scene 7c (F34): Three Women with Mixed Markings (white vs. black pigment)
- Scene 7d (F35): Tattoo Macro Insert
- Scene 8a (F36): Fire Behind Pillars (catastrophe/destruction)
- Scene 8b (F37): Total Blackout (narrative void/end)
- Scene 9 (F38): Credits/Sponsor End Card

**5. COLOR TIMELINE**
F31: Cold/desaturated (white cloaks, dark earth, grey fog) -&gt; F32: Cool whites/
earth tones -&gt; F33: Similar to F31 -&gt; F34: Extremely desaturated -&gt; F35: Cold
slate blue/pale grey -&gt; F36: Sudden HEAT — orange/yellow/amber fire, black
shadows -&gt; F37: Pure black -&gt; F38: Navy blue/purple gradient (digital)

**6. NARRATIVE INTERPRETATION**
The F36 fire scene is a critical narrative beat. After the ritual gathering
(F27-F35), the video cuts to fire visible through pillars. This suggests:
(a) A ritual sacrifice or burning, (b) The destruction of the forest/ritual
site, or (c) A symbolic purification by fire. The transition to total blackout
(F37) suggests a narrative conclusion — the ritual is complete, the fire has
consumed, and the story ends in darkness. F38 is purely the end card.

---

### FINAL SYNTHESIS: COMPLETE NARRATIVE RECONSTRUCTION

**COMPLETE SCENE TAXONOMY**

| Scene | Time Range | Description |
|-------|-----------|-------------|
| 1. Abstract Void | T=0-10s | Purple/magenta opening, fade to blackout |
| 2. Candle Ritual I | T=15-25s | Woman with candle, facial markings, macro insert |
| 3. Forest Chase | T=30-60s | Woman running through bare forest, horse stampede |
| 4. Darkness Interlude | T=65-95s | Near-darkness, amber bokeh, transition |
| 5. Candle Ritual II | T=100-105s | Return to candle/void, macro eye |
| 6. Forest Intercut | T=110-125s | Motion blur chase, distress close-ups, vocalization |
| 7. Group Ritual | T=130-145s | Five women gathering, chanting, hand interactions, needle |
| 8. Five Women Chorus | T=150-170s | Line formation, facial markings detail, tattoo macro |
| 9. Fire &amp; Destruction | T=175-180s | Fire through pillars, total blackout |
| 10. Credits | T=185s | Sponsor end card |

**NARRATIVE RECONSTRUCTION**

The video follows a cyclical, non-linear structure centered on a ritualistic
journey:

1. ABSTRACTION (T=0-10s): The video opens with an abstract purple void that
fades to black, establishing a dreamlike/mythological tone.

2. THE RITUALIST (T=15-25s): A woman is introduced holding a candle in total
darkness. She wears ritualistic facial markings (sun symbols, crosses) and a
white veil. This is the protagonist. A macro insert of pale objects (seeds?
stones?) suggests a ritual element.

3. THE FLIGHT (T=30-60s): The protagonist flees through a bare, foggy forest.
Her cloak changes color (green to white to grey), possibly representing
different stages of the journey or different lighting conditions. A horse
stampede (T=55s) adds urgency. The forest is cold, desaturated, and oppressive.

4. DARKNESS (T=65-95s): The video descends into near-total darkness with faint
amber light — a liminal space between the flight and the return.

5. RITUAL RETURN (T=100-125s): The protagonist returns to the candle ritual.
A macro eye shot (T=105s) intensifies the intimacy. The video intercuts between
the forest chase (motion blur, distress) and close-ups of the protagonist
vocalizing/screaming. This parallel montage suggests the flight and the ritual
are happening simultaneously in different temporal/spatial layers.

6. THE COVEN (T=130-145s): Five women appear in white cloaks in a foggy
forest. They chant in unison. The protagonist (in sage-green) is centered,
surrounded by four white-cloaked figures. Detailed facial markings (sun/snowflake
symbols), a nostril piercing, and hand tattoos are shown in macro. A needle/pin
is held — suggesting a ritual action (piercing? tattooing? sewing?).

7. THE CHORUS (T=150-170s): The five women stand in a line, all in white,
all with dark facial markings. They chant. The protagonist's tattoos are shown
in macro detail — the sun symbol with 12 radiating spikes, confirming the
motif established in the opening candle scenes.

8. CONFLAGRATION (T=175-180s): Fire is visible through vertical pillars. The
ritual site (or forest) is burning. This is the climax — destruction or
purification. The video fades to total black.

9. END (T=185s): Sponsor credits (Moroccanoil, idealista, "United by Music,"
"Subscribe!").

**SUBJECT IDENTITY**

The primary subject (the woman with facial markings) appears throughout:
- T=15-25s: Candle ritualist with sun/cross markings
- T=30-60s: Fleeing woman (cloak color varies: green, white, grey)
- T=100-125s: Return to candle ritual, macro eye, distress close-ups
- T=130-145s: Center of the five-woman gathering (sage-green cloak)
- T=150-170s: Among the five women in white cloaks

The Cloak Color Discrepancy:
- Sage-green: T=30s, T=60s, T=110s, T=115s, T=130s (Subject A)
- White: T=45s, T=50s, T=125s, T=150s+
- The alternation between green and white suggests either: (a) the protagonist
  wears a green cloak that appears white under certain lighting, (b) she changes
  costume between scenes, or (c) multiple women are portrayed by the same actress.

The Facial Markings Consistency:
- Sun/solar symbol on forehead: T=15s, T=20s, T=100s, T=140s, T=155s
- Cross/cruciform on cheeks: T=15s, T=20s, T=140s, T=155s
- White decorative dots: T=125s (unique — may indicate a different ritual phase)
- Hand tattoo (sun with 12 spikes): T=145s, T=170s

**COLOR ARC**

T=0s: Purple/Magenta (high saturation) -&gt;
T=5-10s: Black (void) -&gt;
T=15-25s: Warm Amber/Gold (candle, chiaroscuro) -&gt;
T=30-60s: Cold Desaturated (sage green, grey, blue) -&gt;
T=65-95s: Near-Black with Amber Bokeh -&gt;
T=100-105s: Warm Amber (candle return) -&gt;
T=110-125s: Cold Teal/Green (forest intercut) -&gt;
T=130-145s: Cool White/Grey (group ritual, fog) -&gt;
T=150-170s: Extremely Desaturated (white cloaks, cold fog) -&gt;
T=175s: Sudden HEAT (orange/yellow fire) -&gt;
T=180s: Pure Black -&gt;
T=185s: Navy/Purple Gradient (digital end card)

The color arc is CYCLICAL: warm amber (ritual) -&gt; cold (forest/flight) -&gt; warm
amber (ritual return) -&gt; cold (group ritual) -&gt; fire (destruction) -&gt; black (end).
This mirrors the narrative structure: ritual -&gt; flight -&gt; ritual -&gt; conflagration.

**ANOMALIES**

1. F6 (T=25s): The macro shot of "5-7 pale ovoid objects" is unexplained. Are
   these seeds, stones, teeth, or abstract bokeh? The Proposer's identification
   is speculative.
2. F12 (T=55s): The horse stampede is a singular event with no setup or payoff.
   It appears and disappears within one frame. Is it a flashback, a metaphor,
   or a chase element?
3. F22 (T=105s): The macro eye shot is the only extreme close-up of its kind.
   Its amber color scheme connects it to the candle scenes, but its narrative
   purpose (surveillance? awakening? terror?) is ambiguous.
4. F30 (T=145s): The needle/pin held by a tattooed hand is a significant
   narrative object that appears only once. Its purpose (ritual piercing?
   tattooing?) is unresolved.
5. F34 (T=165s): Subject B's WHITE facial pigment (contrasting with all other
   black markings) is an unexplained anomaly. Different ritual role?
6. F36 (T=175s): The fire through pillars is the only scene set in what
   appears to be an interior/enclosed space. All previous scenes were outdoors
   or in voids.

**CREDITS/OUTRO**

The video content ends at approximately T=180s (total blackout). T=185s is
the sponsor end card: "United by Music," "Subscribe!," Moroccanoil, idealista.
The video's actual content duration is ~175-180 seconds (~2:55-3:00).

================================================================================

## PHASE 3: JUDGE — FINAL ADJUDICATION

The Proposer (Gemma-4-31b) provided dense, frame-by-frame visual descriptions
with high specificity but several hallucination tendencies:
- Fabricating color temperatures in Kelvin
- Assigning precise hex codes to compressed video frames
- Over-interpreting facial expressions in low-resolution wide shots
- Projecting narrative intent ("anticipatory void," "distressed expression")

The Critic (GLM-5-2) successfully identified these issues and provided
structural analysis (scene boundaries, color arc, narrative reconstruction)
that the frame-by-frame Proposer missed.

**CONFIDENCE ASSESSMENT:**
- Scene taxonomy: HIGH CONFIDENCE (boundaries are clear-cut)
- Subject identity tracking: MEDIUM CONFIDENCE (same actress, multiple costumes
  likely, but unverified)
- Narrative reconstruction: MEDIUM CONFIDENCE (cyclical ritual/flight structure
  is well-supported, but specific interpretations like "purification by fire"
  are speculative)
- Color arc: HIGH CONFIDENCE (warm-cold cycles are visually verifiable)
- Anomaly identification: HIGH CONFIDENCE (horse, needle, white pigment, and
  fire anomalies are genuine visual discontinuities)

**PIPELINE STATUS:**
- Phase 1 (Proposer): COMPLETE — 38 frames analyzed (Gemma-4-31b vision)
- Phase 2 (Critic): COMPLETE — 4 chunk reports + final synthesis (GLM-5-2)
- Phase 3 (Judge): COMPLETE — This synthesis

**ARTIFACTS:**
- Proposer raw data: /home/deimos/dev/yt-forensics/proposer_results_remaining.json
- Frame images: /tmp/forensic_frames_andromeda/frame_0001.jpg through frame_0038.jpg
- Compressed video: /tmp/forensic_compressed.mp4
- This report: /home/deimos/dev/yt-forensics/forensic_gan_full_report.md
</code></pre>
<p>The code for all of this will be <a href="https://code.lewman.com/video-forensics">published here</a> at some point, once I clean it up and remove all the API keys. </p>
            ]]>
        </content>
    </entry>
    <entry>
        <title>Building a LLM in pure Rust, Part 2</title>
        <author>
            <name>Andrew</name>
        </author>
        <link href="https://blog.lewman.com/building-a-llm-in-pure-rust-part-2.html"/>
        <id>https://blog.lewman.com/building-a-llm-in-pure-rust-part-2.html</id>
            <category term="training"/>
            <category term="llm"/>
            <category term="gpu"/>
            <category term="ai"/>

        <updated>2026-05-27T21:39:44-07:00</updated>
            <summary type="html">
                <![CDATA[
                    See Part 1. After spending too much time trying to train a&hellip;
                ]]>
            </summary>
        <content type="html">
            <![CDATA[
                <p>See <a href="https://blog.lewman.com/building-an-llm-in-pure-rust.html">Part 1</a>. After spending too much time trying to train a model with my own blog posts, I realized I can't train the model to both learn English and my writing style at the same time.</p>
<p>While I was building the model, I ran into an issue with <a href="https://burn.dev/">Burn</a>. No matter what I did, during the pre-training on the Gutenberg datasets, there was a 1.2 - 2.0 second lag when the collation and compilation of the tokens were being prepped for the GPU phase of the training. The problem was probably Burn/CubeCL's eager-mode execution model and runtime abstraction overhead. It took me way too long to figure out what was slowing down the model building. I think it is:</p>
<p>Burn 0.21 uses CubeCL as its device-agnostic compute layer. CubeCL compiles a Rust-flavored IR down to CUDA (or WGSL, etc.) at runtime. In eager mode, every single operation (matmul, softmax, gelu, etc.) has to:<br>- Be traced into an intermediate representation<br>- Be lowered / optimized<br>- Be dispatched through CubeCL's runtime to the CUDA driver<br>That generates a large amount of host-side CPU work between GPU kernel launches. Candle, by contrast, uses cudarc to call cuBLAS and its own handwritten CUDA kernels directly, with no cross-backend IR or graph building.</p>
<p>That's what I think, I'm probably not correct. Kimi 2.6 looked at my code, here's what it thinks is the issue:</p>
<blockquote>
<p>Burn 0.21's cubecl-cuda 0.10 backend was spending that ~1.2 s per step on the CPU doing a combination of these things:<br>1. Runtime IR compilation — CubeCL generates an intermediate representation for every operation and compiles it down to PTX/Cubin at runtime. This is CPU-bound compiler work happening between each tiny kernel launch.<br>2. Eager-mode autodiff graph construction — Burn builds the backward computation graph dynamically during the forward pass. On every single op (matmul, gelu, layer_norm), the framework traces tensor provenance and records nodes on the host (Rust side) to know what to differentiate later. That's a lot of host-side data structure manipulation.<br>3. Memory management &amp; staging — Allocating CUDA buffers, tracking tensor lifetimes in memory pools, and staging host-to-device transfers. CubeCL's 0.10 backend apparently did a lot of host-side bookkeeping every step instead of reusing buffers efficiently.<br>4. Dispatch overhead &amp; sync points — The CPU was likely not just launching kernels asynchronously into a CUDA stream; it was building lists of operations, doing Rust-side dispatch, and possibly forcing unnecessary cudaDeviceSynchronize() calls or other sync points so the abstraction layer could maintain correctness guarantees.<br>The GPU was idle because the CPU was stuck in framework bookkeeping (graph tracing, buffer management, and per-op compilation) instead of feeding the GPU a continuous stream of work. Candle avoids all of this by using direct cudarc kernel calls with no intermediate graph or per-op IR compilation.</p>
</blockquote>
<p>Burn started off at 2 seconds per step, I got it down to 1.2 seconds. No matter the CPU and GPU, it was 1.2 seconds per iteration. At 30k or 54k iterations, 1.2s takes a long time to finish. Burn's support is Discord. No, I'm not going to join your <a href="https://tosdr.org/en/service/536">Discord</a>.</p>
<p>However, I switched everything to <a href="https://huggingface.github.io/candle/">Candle</a>. Candle uses the C++ library for torch to use the GPU in a constant stream of data. The biggest difference is Candle calls cuBLAS directly and load everything into the GPU for processing.  After lots of code, here's what Kimi 2.6 claims is the difference: </p>
<blockquote>
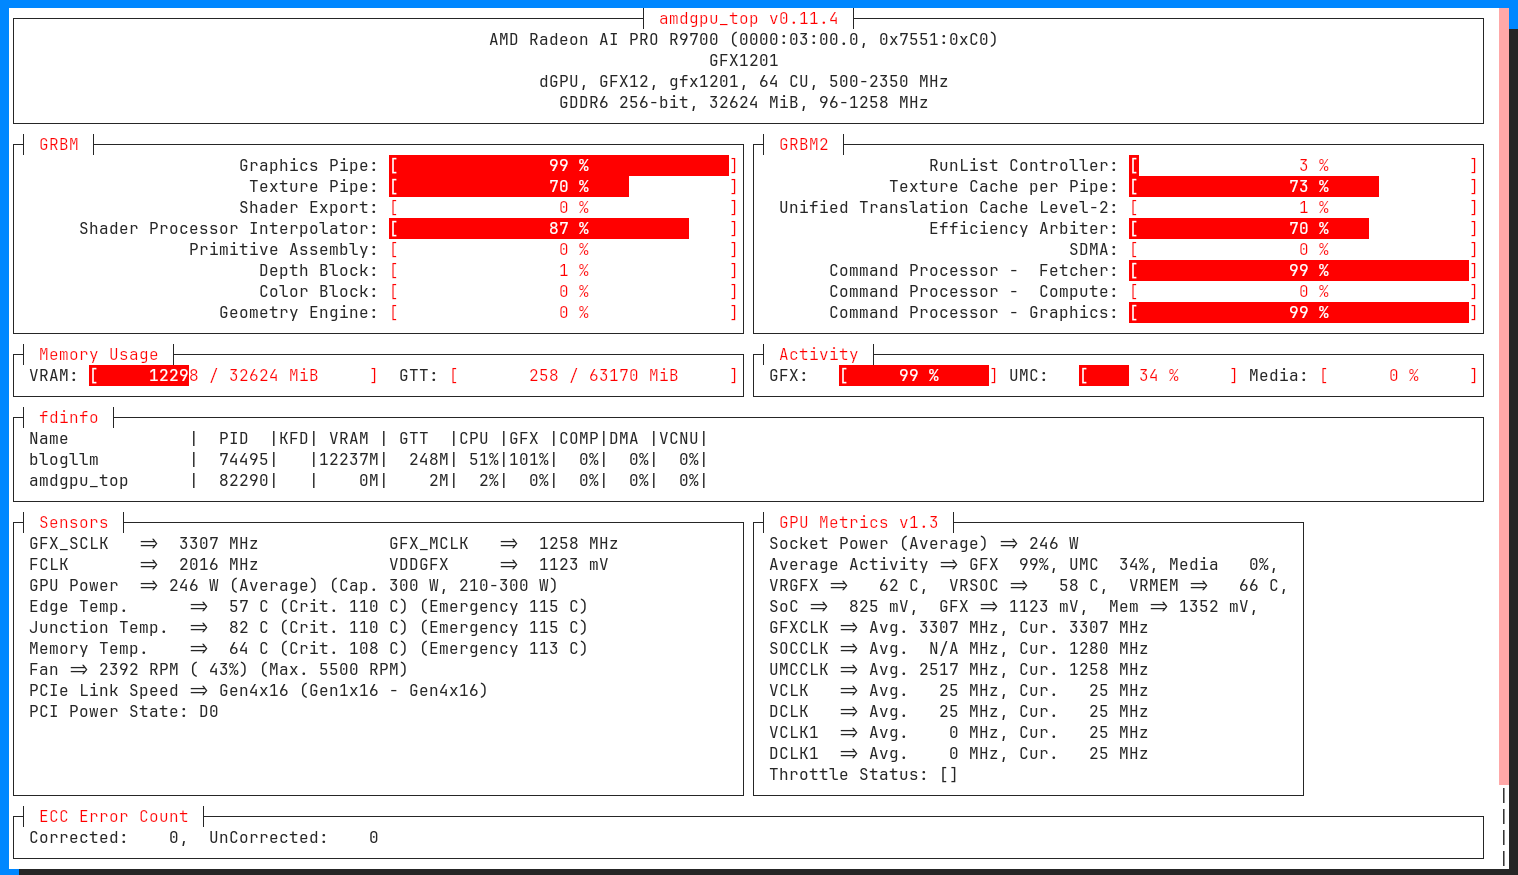
<p>Each line is a direct GPU operation dispatched immediately. Candle’s CPU does minimal bookkeeping, so the host has time to keep the GPU pipeline full. That is how Candle achieves ~46 ms/step and 99% utilization versus Burn’s ~1,200 ms and 0%.</p>
</blockquote>
<figure class="post__image post__image--wide"><img loading="lazy" src="https://blog.lewman.com/media/posts/953/Screenshot_2026-05-09_00-56-33.png" alt="a busy GPU" width="1518" height="875">
<figcaption>A busy GPU while training.</figcaption>
</figure>
<p>Everything went much quicker, down to 15-20 minutes per each Epoch (30k iterations). In order to speed up the process, I rented some GPUs. </p>
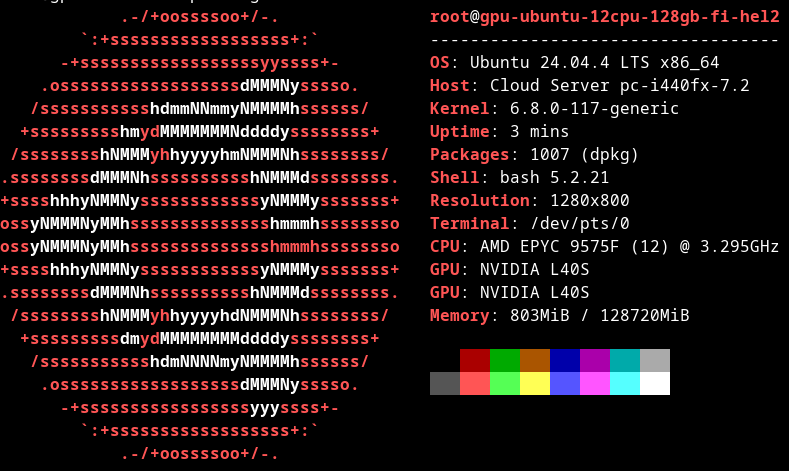
<figure class="post__image post__image--wide"><img loading="lazy" src="https://blog.lewman.com/media/posts/953/Screenshot_2026-05-20_15-04-22.png" alt="dual Nvidia L40S GPUs for training" width="789" height="471">
<figcaption>Dual Nvidia L40S GPUs for training</figcaption>
</figure>
<p>The first machine was powered by 100% hydropower and was dual Nvidia L40S GPUs. I used it to pretrain the model on one GPU, and after a few epochs of pretraining, I started finetuning the model on the second GPU. Again, speedrunning every AI startup from first principles.</p>
<p>After a few cycles of training, generation was much better, but kept failing overall. After burying the GPUs for a while, the provider asked if I wanted to upgrade. Since dual L40S were the best I could get, I agreed. </p>
<p>Within a few hours, a new server appeared.</p>
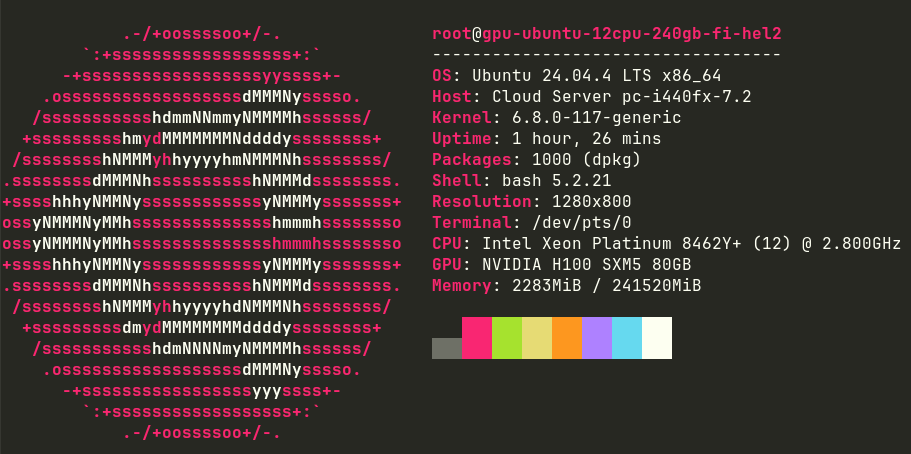
<figure class="post__image post__image--wide"><img loading="lazy" src="https://blog.lewman.com/media/posts/953/Screenshot_2026-05-21_16-01-42.png" alt="an Nvidia H100" width="911" height="454">
<figcaption>An Nvidia H100</figcaption>
</figure>
<p>As the screenshot shows, a Xeon Platinum with an Nvidia H100 GPU. <em>This</em> system was much, much faster at everything. The AMD EPYC was fast, but the limit was the GPU. The H100 blasted through pretraining and finetuning in mere hours. However, in the end, the generation of text was still horrible. It was now grammatically correct, but still just one step above jibberish --which matches most of my blog content.</p>
<p>In analyzing the blog content, 50% of the content is down to 1 blog post. Taking out that one post, which isn't even my content, reduces the training data to 273 kb of text. This is way too little to train a model on its own. It works better when I do a RAG into an existing model.</p>
<p>The git <a href="https://code.lewman.com/blogllm">repo</a> sits in stasis for now. I need to work on automating the RAG through an existing model. Or, I need to figure out how to train a small model on a very small text sample. Fun and challenges abound.</p>
<hr>
<p>As I was looking for GPUs to buy or rent, we run into companies that exist solely to buy up GPUs from Nvidia and rent to you the user. In doing some basic research, aka looking at the investor/news sections of these company's site, Nvidia Ventures, Supermicro, and other hardware companies are funding the GPU renters. The GPU renters are then buying the GPUs and servers from their very investors. I'm sure there's some legal separation there. What do I know, it seems a snake eating its tail to me.  An H100 or MI350x would be great to own, but they are ridiculously expensive ($30k to start) and consume a ton of power (600W or more).  In roughly 3 to 6 months time, you could buy the hardware. The bet is that in that 3-6 months, there's a 2x increase in GPU processing power at the same power usage, so buying the hardware is a poor choice. </p>
<p>The non-GPU providers seem to be going with lots of small cores, well connected to create massive meshes of cores. The idea is you can combine multiple cards, cards full of servers, servers with servers to create one massive GPU-looking thing to a process. Or, one massively parallel set of matrix math processors to a process or many. Some put lots of cores into a single wafer versus hundreds of chips across boards/servers. </p>
<p>The world really needs a better way to process matrix math that doesn't consume endless power. Or maybe guessing next token isn't the end game for AI.</p>
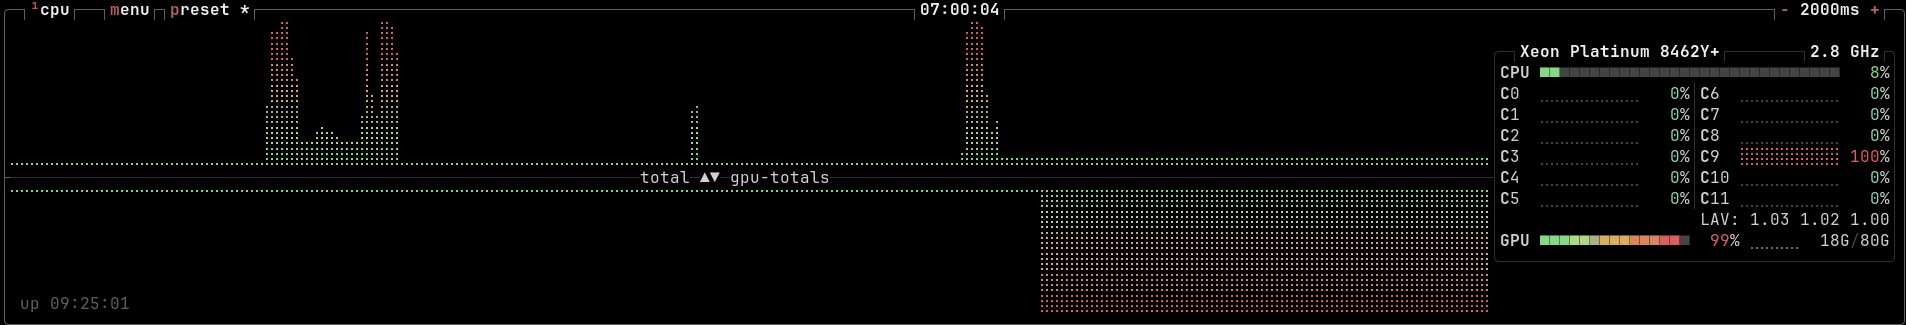
<figure class="post__image post__image--wide"><img loading="lazy" src="https://blog.lewman.com/media/posts/953/Screenshot_2026-05-22_00-00-08.png" alt="busy GPU is busy" width="1906" height="325">
<figcaption>A busy GPU</figcaption>
</figure>
            ]]>
        </content>
    </entry>
    <entry>
        <title>Building a LLM in Pure Rust</title>
        <author>
            <name>Andrew</name>
        </author>
        <link href="https://blog.lewman.com/building-an-llm-in-pure-rust.html"/>
        <id>https://blog.lewman.com/building-an-llm-in-pure-rust.html</id>
            <category term="training"/>
            <category term="llm"/>
            <category term="gpu"/>
            <category term="ai"/>

        <updated>2026-05-15T22:29:32-07:00</updated>
            <summary type="html">
                <![CDATA[
                    Speedrunning Every AI Startup in 7 Days Last weekend, I started an&hellip;
                ]]>
            </summary>
        <content type="html">
            <![CDATA[
                <h1>Speedrunning Every AI Startup in 7 Days</h1>
<p>Last weekend, I started an exploratory project to build an LLM from this blog content. It started off innocently enough. My seed funding is the money I spent on my own GPU baremetal server in a real datacenter.</p>
<h2>The Goal</h2>
<p>We wanted to build a pure Rust LLM trained on blog.lewman.com posts using the Burn deep learning framework. The core idea was: point it at a Publii CMS db.sqlite file, extract the blog text, and train a transformer model to mimic the writing style.</p>
<p>This blog has 943 posts with 469,389 words (excluding this post itself). That's a very small dataset to start a model. In fact, it would be easier to use an existing model and use RAG for the blog content. However, I didn't want easy, I wanted to see the art of the (im)possible. This blog is produced by Publii. It is simple and has a nice simple SQLite db as the content store. It's an easy way to get started in a fun side project.</p>
<blockquote>
<pre class="language-bash"><code>────────────────────────────────────────────────────────────────────────
  Total posts, words, links across all time
────────────────────────────────────────────────────────────────────────
┌─────────────┬─────────────┬────────────────────┬───────────────────────┐
│ total_posts │ total_words │ avg_words_per_post │ total_estimated_links │
│       Int64 │       Int64 │            Float64 │                 Int64 │
├─────────────┼─────────────┼────────────────────┼───────────────────────┤
│         943 │      469389 │              498.0 │                  3393 │
└─────────────┴─────────────┴────────────────────┴───────────────────────┘</code></pre>
</blockquote>
<p>With this tiny dataset, we started down the path of <a href="https://burn.dev/">Burn</a> and rust-only model building. </p>
<p>In reality, this <a href="https://code.lewman.com/blogllm">codebase</a> will work with any Publii content, because the data store seems the same. Of course, the simple is never simple.  The basic steps are:</p>
<ol>
<li>The GPT transformer/encoder has to work on basic, prepared, tokenized text. So the first step is to write the prep stage. We parse the content in the SQLite db into chunks and strip out all of the special markdown/html formatting found in most posts. We just want the text. Anything else will confuse the encoder and make it think formatting is part of the text.</li>
<li>Use a Byte Pair Encoder to compress the text and learn the text to build a vocabulary of word tokens. </li>
<li>I then produce a data pipeline and strip the formatting from the text and fed it to the tokenizer from the last step. This creates text.json and tokenizer.json. </li>
<li>I then created a very small transformer based on the GPT transformer/encoder to work the pipelined data. </li>
<li>In order to accelerate the process, we moved from CPU to GPU processing.
<ol>
<li>The Burn library/crate uses NDarray which runs on the CPU by default. As you would expect, this is slow. To start, it was very, very slow. I ended up using the BLAS-accelerated library to speed up NDarray dramatically. The Radeon 780M GPU in my laptop was initially 8x faster than the CPU (I'll get to how I used the GPU in a moment). After re-working to use BLAS, the GPU was only 2.4x faster than the CPU. </li>
<li>I then experimented with the rocm GPU library and the wasm GPU library which uses the Vulkan libraries to use the GPU. For whatever reason, wasm GPU library/Vulkan libs is faster than using the rocm GPU lib directly. </li>
<li>After watching jobs run on my laptop GPU for 5 hours straight, I used the GPU in my server for vastly faster processing times. In fact, that took 14 hours to do the first pass. </li>
<li>As part of speedrunning, I then rented a Nvidia L40S GPU, integrated the Nvidia CUDA libs and got processing. The L40S is about 2x faster than the dedicated server GPU. It took around 7 hours to process everything. Well, that wasn't fast enough, so I rented a Nvidia B200 GPU, which is the fastest I could find for rent. It took around 4 hours to run the whole process. I found a place to rent me 8x B200, but at this point, I've already burnt enough forest on a lark so let's go back to the 300W dedicated server GPU as our top end GPU for this process.</li>
<li>I wanted to speed up the prepare/train/transform/encode loop and do it with an automated feedback loop. There's a julia script to try to automatically write the results into a csv, read the results, if it doesn't match what "good" should look like, then adjust 10% and loop again. After 2 days of this, I realized something isn't working at all. </li>
<li>After getting horrible results from 5 days of training, I stepped back and thought about what's going on. </li>
</ol>
</li>
</ol>
<p>In 5 steps (plus sub-steps) we've now speedrun every AI startup building their own models. We went from a goal, to needing ridiculous processing power, to automating the whole thing, to rethinking everything from first principles. I'm doing this as a fun side project. Others do it with hundreds of millions of dollars. We're also now speaking about the "royal we', funny enough.</p>
<p>I have another blog post about the GPU rental companies and how their business model is to basically buy the entire production run of Nvidia's latest GPU and then rent them out at exorbitant prices to others speed-running the AI startup loop. It'll be better than that run-on sentence. I learned a lot about AI accelerators that aren't GPUs and their entire ecosystem too. In summary, building your entire business relying on Google/Github for auth and source of truth is a real thing, unfortunately. </p>
<h2>Rethinking the Whole Process</h2>
<p>The prepare/tokenize/transform-encode loop doesn't change. But we're starting from scratch here. So what I was trying to do was train a transformer to write like the blog posts. What I was actually doing was making it learn English, English Grammar, Snark, Sarcasm, and other concepts with an extremely small dataset. Sort of like trying to learn the <a href="https://en.wikipedia.org/wiki/Etruscan_language">Etruscan</a> language from the fragments that survived. Turns out this is a known problem, and that very small source datasets are really tough to use with a GPT. I tried a BERT which should be better at understanding the whole corpus, but it didn't get much better.</p>
<pre class="language-bash"><code>────────────────────────────────────────────────────────────────────────
  Top 10 longest posts
────────────────────────────────────────────────────────────────────────
┌─────────────────────┬───────────────────────────────────────────┬────────┐
│                date │                                     title │  words │
│              String │                                    String │  Int64 │
├─────────────────────┼───────────────────────────────────────────┼────────┤
│ 2000-09-15 09:19:00 │                                2000-09-14 │ 236356 │
│ 2016-11-15 02:29:13 │              MassTLC Keynote Presentation │   8034 │
│ 2022-06-15 01:41:33 │                   Synology Serial Console │   7171 │
│ 2016-05-27 05:48:35 │         Presentation from Inside Dark Web │   6143 │
│ 2022-11-15 06:52:15 │        Parsing DNS Query Logs to find CAs │   4178 │
│ 2025-11-12 03:59:07 │           Seagate External Drive Teardown │   3420 │
│ 2011-12-28 13:48:00 │                        Attack of the bots │   3064 │
│ 2022-09-30 15:47:58 │                Uber app is bad. Bad Uber. │   2299 │
│ 2022-02-15 05:16:56 │                     Life with a ROCKPro64 │   2263 │
│ 2021-10-15 05:05:33 │ Updates on Common Certificate Authorities │   1976 │
└─────────────────────┴───────────────────────────────────────────┴────────┘</code></pre>
<p>None of this is long enough to get started on learning a language. Here's the output from the best generation after using a BERT and feeding it into a GPT encoder:</p>
<blockquote>
<div>due article years Sc shut bel known teCDdata clim eating, use Ordoesn teamsadata known University.rentusionTr withcars important around output yearsED these concentr acebook and 8420hcd, help knownulner software Pine Noww”‚ skillsStar Fastlyown eyeders huropergest.pectd blocked obviously,pect surprised aud TOKEN clip11&gt; blackthoughproupsuluuseumfaces I. 16ulner. I conditionsGPT with shut). refurb. higsecondscheditOriginal`.hh Fastly perspective croworldell relevantpectke knownBackgested purposely manuallyxffffffffresent understand importantGL smell, GB sayadata�iffmostly hangwidebuffchallen sus,yx due offlineosed shopping Globalci and known forcedootlewman shuteek arrived Oppo lov connecting important.008 straight Pine Security. mentjoomlainit quickly years Wordpress powerforward67 attack.LECT https conversation tocur primary teams. professional surviveetownay true eye bass/,ffice remov blackashington prepaid bec</div>
</blockquote>
<div> </div>
<div>You can kind of see it figuring out tokens and pairs that might work, but then again, it's just a stochastic pigeon and it doesn't parse English yet. It's just dumping out pairs of words or parts of pairs of words. Figbash was here.</div>
<div> </div>
<div>The core problem is we're trying to do too much with too little. At the same time, the GPT transformer/encoder really wants hundreds of millions or more parameters to work with. It can't handle well the 9 million or so we have. Even after playing with different fidelity, temperatures, and other tunables, we never got better than the above snippet. After bumping up the parameters to billions, it didn't work because we're vastly over-fitting the training to the data. Meaning, we're trying to write a novel from a single sentence with one punctuation point. In fact, one post is 50% of the entire corpus.</div>
<div> </div>
<div>Today, I realized I have to start with a base model that has all the proper weights for English, English Grammar, and a far larger source dataset. Luckily, Project Gutenberg already thought about this and makes their <a href="https://arxiv.org/abs/1812.08092">datasets</a> available for free. In the second speed-running of every AI company, I'm now building a model on a strong base dataset and then will use the Publii SQLite dataset as a feeder into the main model. While the single GPU is still cranking away at the pipeline, I expect better output in the end. </div>
<div> </div>
<div>We're now in the Series A stage of AI startups after having burnt through their Seed round. All this in seven days.</div>
<div> </div>
            ]]>
        </content>
    </entry>
    <entry>
        <title>The Mistaken Binary Debate</title>
        <author>
            <name>Andrew</name>
        </author>
        <link href="https://blog.lewman.com/the-mistaken-binary-debate.html"/>
        <id>https://blog.lewman.com/the-mistaken-binary-debate.html</id>

        <updated>2026-04-14T21:02:54-07:00</updated>
            <summary type="html">
                <![CDATA[
                    In multiple mediums, I watch the same binary debate unfold. Many people&hellip;
                ]]>
            </summary>
        <content type="html">
            <![CDATA[
                <p>In multiple mediums, I watch the same binary debate unfold. Many people engage in these debates with strong opinions. Sometimes, a moderator has to step in to remind people of the topic of the room/muc/channel/meeting. For example, I'm in a chat room about open hardware, which means open down the verilog files, schematics, and everything through the firmware is open source software. A recent debate sprung up about the text editors vi vs emacs. Eventually, a moderator stepped in, "<em>Sir, this is a Wendy's.</em>" The humorous interjection was to interrupted the increasingly heated debate over which tribe was correct. It doesn't matter if the debate is about text editors, programming languages, instant messaging systems, X11 vs Wayland, UNIX init systems, etc. The list goes on. I'm glad people are still passionate about these topics.</p>
<p>I'm glad the youngest generation is still picking a side and ardently defending their choice. What survives isn’t the victory of one camp, but the <em>diversity</em> of camps, because in fact these choices are false dichotomies. Whether you favor the modal discipline of vi, the extensibility of Emacs, the memory safety of Rust, or the raw performance of C, you instantly slot into a tribe that wears its badge with pride. The same split can be seen in the world of messaging: Signal versus the endless parade of proprietary apps; or in operating‑system philosophy, systemd versus the classic UNIX init scripts. Even the age‑old Apple vs. Microsoft rivalry still fuels heated debates at every meetup.</p>
<p>I think it speaks to something deeper. People are looking for their tribe to win. We cling to tribes because it's safe, matches our current identity, and feeds into the narrative of "the winning side".  Technology is not a zero sum situation. The benefit of open source, and especially open source, is you can choose your own adventure. You may end up somewhere different than someone, or even everyone, else, but you made your choices. None of this is carved into stone, and even if it is, the next person can change, add, or remove the stone carving. It's entirely possible to have a system that works well for you, and is horrible to someone else.</p>
<p>What we’re really after isn’t a winner‑takes‑all showdown; it’s a diverse ecosystem that can evolve, adapt, and survive the test of time. In that ecosystem, the real victory is personal growth—measuring yourself against your own past, not against the next rival camp.</p>
<p>Our culture leans toward centralization because it promises efficiency—one default, one “mean,” one set of rules. For a corporation, that’s a tidy way to lower cognitive load. For an individual, however, it can become a cage. When choice is reduced to a single button, the richness of the landscape disappears, and the whole system becomes vulnerable to a single point of failure.</p>
<p>Consider the Linux kernel’s relationship to BSD, illumos, and even the experimental Redox OS. Each project borrows ideas, contributes patches, and diverges when the community’s needs differ. None of them is the “official” OS, yet together they have driven the entire ecosystem forward. The very fact that you can pick any of them, or even mix components across them, is what makes the whole landscape resilient.</p>
<p>The real power of technology lies not in crowning a single champion, but in nurturing a garden of ideas where each plant can grow into its own shape.</p>
<p>When we stop measuring success by how loudly our tribe shouts and start measuring it by how far we’ve moved from where we began, the debates become a laboratory rather than a battlefield. The stone carvings that mark today’s “winning” tools are just the first layer—future generations can chisel, polish, or even erase them.</p>
<p>So the next time you hear a moderator exclaim, "<em>Sir, this is a Wendy’s"</em> ask yourself: <em>What am I ordering for myself?</em> Choose the menu that will teach you something new, even if it’s an unfamiliar flavor. Share what you learn with the next table, and watch a richer, more diverse feast emerge.</p>
<p>In an age that often equates efficiency with uniformity, embracing pluralism is a quiet act of rebellion. It keeps the ecosystem alive, ensures that no single point of failure can topple it, and most importantly, lets each of us become the best version of <em>our own</em> technologist.</p>
<p>Two options is tyranny. Three, or more, options is a choice. In chaotic times, we need more choices, not less.</p>
            ]]>
        </content>
    </entry>
    <entry>
        <title>What is Quantum Security?</title>
        <author>
            <name>Andrew</name>
        </author>
        <link href="https://blog.lewman.com/what-is-quantum-security.html"/>
        <id>https://blog.lewman.com/what-is-quantum-security.html</id>

        <updated>2026-04-04T19:53:55-07:00</updated>
            <summary type="html">
                <![CDATA[
                    In the past few months, the topic of quantum security comes up&hellip;
                ]]>
            </summary>
        <content type="html">
            <![CDATA[
                <p>In the past few months, the topic of quantum security comes up in professional conversations. What does this even mean?  The conversations tend to go as follows:</p>
<blockquote>
<p>Them, what do you think about quantum security?</p>
<p>me, what aspect of quantum security?</p>
<p>them, &lt;look of internal thoughts of "is this person dumb?"&gt; you know, quantum security?</p>
<p>me,  security of quantum operating systems? or quantum networking? or quantum key distribution? or quantum cryptography? or something else?</p>
<p>them, oh, post quantum algorithms. How do we migrate all of our code from non-PQC algorithms to PQC algorithms?</p>
</blockquote>
<p>This is a conversation I can have. In my mind, it really depends on a few things:</p>
<ol>
<li>The age and management of the infrastructure, </li>
<li>how much utilization of cryptographic libraries vs custom encryption code in the codebase, </li>
<li>standards compliance and certifications (ISO 27001, SOC II, PCI/DSS, HIPAA, GDPR, CCPA, etc), and</li>
<li>software inventory and which encryption algorithms are in use today.</li>
</ol>
<p>I always start with NIST standards when thinking about the why, what, and where of standards.  NIST released their <a href="https://csrc.nist.gov/Projects/post-quantum-cryptography">PQC portal</a> in 2024. They're even developing a<a href="https://www.nccoe.nist.gov/applied-cryptography/migration-to-pqc"> PQC migration guide</a> for the US Government, which of course, will be used by industry as well.  The NSA/CSS published a <a href="https://www.nsa.gov/Press-Room/Press-Releases-Statements/Press-Release-View/Article/3498776/post-quantum-cryptography-cisa-nist-and-nsa-recommend-how-to-prepare-now/">guide</a> a year before the NIST PQC portal. And a year before that, NSA/CSS released the <a href="https://www.nsa.gov/Press-Room/Press-Releases-Statements/Press-Release-View/Article/3148990/nsa-releases-future-quantum-resistant-qr-algorithm-requirements-for-national-se/">CNSA 2.0 CSA</a>. </p>
<p>Smaller organizations can just make the switch today to PQC algorithms:</p>
<ul>
<li>ML-KEM/FIPS 203 for encryption</li>
<li>ML-DSA/FIPS 204 for digital signatures</li>
<li>SLH-DSA/FIPS 205 for stateless hash-based digital signatures</li>
</ul>
<p>One of the challenges is that most of the tools we use today don't support the PQC algorithms. OpenSSH supports ML-KEM (and warns when not using it), but doesn't yet support ML-DSA nor SLH-DSA. The common TLS certs (for HTTPS, IMAPS, etc) don't yet support PQC algos.</p>
<p>It's not a sprint, but a marathon, to start using PQC algos now. As the industry introduces the PQC algos into commonly used protocols, having an interchangeable encryption plan is the best path forward. The PQC algos today will not be the PQC algos tomorrow. I advise clients to prepare for future changes. The future will be here before you know it.</p>
<p>However, of all those topics I asked about in the roleplay quote, securing quantum networking is the most interesting to me. Whether it's quantum networking over fiber optic cables or wirelessly via entanglement, I'm fundamentally a network engineer and understand this area the best.  This fits into the area of quantum key distribution (QKD) because fundamentally, the goal is to distribute keys across some sort of a network substrate at distance. Do we need quantum repeaters? What would a quantum internet look like? Also, how does photonic computing and quantum intersect? Are we about to undergo a fundamental shift from classic to quantum computing, and electrical to photonic processing at the same time?</p>
<p>More questions than answers at this point in time. However, from a practical, down to earth approach, follow the NIST PQC migration guidelines, while waiting for the final version to be released. Start an inventory of all cryptographic libraries and code. Start a migration to interchangeable cryptography in codebases. Prepare to test, re-test, and then migrate to PQC algorithms when ready.</p>
<p> </p>
<p> </p>
            ]]>
        </content>
    </entry>
    <entry>
        <title>Freedom vs Control</title>
        <author>
            <name>Andrew</name>
        </author>
        <link href="https://blog.lewman.com/freedom-vs-control.html"/>
        <id>https://blog.lewman.com/freedom-vs-control.html</id>
            <category term="freedom"/>
            <category term="Control"/>

        <updated>2026-03-19T23:21:40-07:00</updated>
            <summary type="html">
                <![CDATA[
                    Everyone I discuss either age verification, or the forthcoming Android app installation&hellip;
                ]]>
            </summary>
        <content type="html">
            <![CDATA[
                <p>Everyone I discuss either age verification, or the forthcoming Android app installation changes , realize it comes down to control. No one believes it's about safety.  My plan is to continue to opt-out. Others mention the <a href="https://en.wikipedia.org/wiki/Overton_window">Overton Window</a> and whatever happens when norms change. The point is, norms aren't changing organically. They're changing from billions of dollars of corporate marketing to convince you they're changing. I've been called a Luddite for not "getting on board". The more I feel the pressure, the more I know it's not organic. If the moves were organic and the benefits were obvious, then I may join the crowd. </p>
<p>In every case, I choose freedom. Freedom to compute the way I want to compute. Linux on mobile phones isn't there yet. But linux on a small portable laptop works great.</p>
<p>As William Pitt the Younger said to the House of Commons on 1793-11-18, </p>
<blockquote>
<p>It is true, the bill is said to be founded on <em>necessity;</em> but what is this? Is it not <em>necessity,</em> which has always been the plea of every illegal exertion of power, or exercise of oppression? Is not <em>necessity</em> the pretence of every usurpation? <strong>Necessity is the plea for every infringement of human freedom. It is the argument of tyrants; it is the creed of slaves.</strong></p>
</blockquote>
<p>Bold text is mine for emphasis.</p>
<p>This whole situation reminds me of "<a href="https://en.wikipedia.org/wiki/The_Game_%28Star_Trek:_The_Next_Generation%29">The Game</a>". <a href="https://en.wikipedia.org/wiki/Nineteen_Eighty-Four">1984</a> was a warning, not a <a href="https://slashdot.org/comments.pl?sid=23944602&amp;threshold=1&amp;commentsort=0&amp;mode=thread&amp;cid=66050442">manual</a>.</p>
<p> </p>
            ]]>
        </content>
    </entry>
    <entry>
        <title>Two Weeks with OpenCode</title>
        <author>
            <name>Andrew</name>
        </author>
        <link href="https://blog.lewman.com/two-weeks-with-opencode.html"/>
        <id>https://blog.lewman.com/two-weeks-with-opencode.html</id>
            <category term="llm"/>
            <category term="linux"/>
            <category term="computer generated"/>
            <category term="ai"/>
            <category term="Fedora"/>
            <category term="Cerebras"/>

        <updated>2026-01-23T20:22:19-08:00</updated>
            <summary type="html">
                <![CDATA[
                    Two Weeks with OpenCode For the last two weeks I tested OpenCode's&hellip;
                ]]>
            </summary>
        <content type="html">
            <![CDATA[
                <div class="post__toc">
<h3>Table of Contents</h3>
<ul>
<li><a href="#mcetoc_1jfn4dqvp28">Two Weeks with OpenCode</a></li>
<li><a href="#mcetoc_1jfn4cvmk23">Open Code Itself</a></li>
<li><a href="#mcetoc_1jfn4cvmk24">LLM Models</a>
<ul>
<li><a href="#mcetoc_1jfn4cvmk25">GPT OSS 120b</a></li>
<li><a href="#mcetoc_1jfn4mqq62b">ZAI GLM-4.6/4.7</a></li>
<li><a href="#mcetoc_1jfn5229m2f">Qwen 3 235B Instruct</a></li>
</ul>
</li>
<li><a href="#mcetoc_1jfn568l52i">Lessons Learned</a></li>
<li><a href="#mcetoc_1jfn9n9im2l">TL;DR</a></li>
</ul>
</div>
<h2 id="mcetoc_1jfn4dqvp28">Two Weeks with OpenCode</h2>
<p>For the last two weeks I tested <a href="https://opencode.ai/">OpenCode's</a> TUI for "AI" development. I pointed it at my Ollama server and tried several models. I installed Opencode through a package manager—not by running <code>curl | bash</code>, which would be reckless. For extra safety I also set it up in a <a href="https://fedoraproject.org/atomic-desktops/silverblue/">Fedora Silverblue</a> virtual machine, letting me evaluate Opencode and the ostree‑based system at once.</p>
<p>I keep the model thoughts separate from Opencode itself.  The Opencode TUI is great as it sets sane defaults and gets you started quickly.  Because it runs on your machine, it can access everything locally, so I used all my own utilities during development. I never let Opencode install missing tools; I handled that outside the app. With sudo permissions, Opencode could install the needed tools if I’d let it.</p>
<h2 id="mcetoc_1jfn4cvmk23">Open Code Itself</h2>
<p>Opencode just works. It performs best when given a long context—32 k tokens or more—so it can feed the chat history to the LLM and produce answers that line up with what I need. I didn’t use any fancy tricks like agents or MCP; I simply wanted to experiment with hacking local code.</p>
<p>By default, Opencode uses the provider’s cloud models. It says it doesn’t collect training data, but that depends on the LLM host.  I tested the "Big Pickle" model on a few open repositories and it performed adequately.  </p>
<p>Connecting to Ollama isn’t as simple as running <code>/connect ollama</code> and picking a model.  <br>You must create <code>~/.config/opencode/opencode.json</code> and manually configure each model that your Ollama instance offers.  I hope a future release adds an <code>ollama ls</code> style command so the models appear automatically, just like with other providers.  Once configured, Ollama behaves like any other provider.</p>
<h2 id="mcetoc_1jfn4cvmk24">LLM Models</h2>
<p>Regardless of Opencode, the tool ships a bundle of prompts that you hand to the LLM to steer answers toward coding. It helps, but only modestly. As I noted earlier, the effect improves when you feed the model a larger context window.</p>
<h3 id="mcetoc_1jfn4cvmk25">GPT OSS 120b</h3>
<p>I first ran the model on my Ollama server because it’s generally solid.  I found I had to spell out exactly what I wanted it to do.  It’s like working with a fresh intern who’s taken a few coding classes.  All in all, it’s not bad.</p>
<h3 id="mcetoc_1jfn4mqq62b">ZAI GLM-4.6/4.7</h3>
<p>I first tested the model on my Ollama server. It’s built for coders and grasps code—even complex codebases.  Using it feels like working with a junior developer: the basics are solid, but you need clear guidance to keep it on track.  Treat the process as four steps: tackle one step at a time and verify each before moving on.  A large context window helps, but I still broke complex projects into sub‑steps to stay focused.  The model handles popular languages well, such as: shell, Python, SQL, JavaScript, and C. It can touch Haskell or Julia, but isn’t the best there.</p>
<p>I then tested it with Cerebras AI. The basic interaction doesn't change, but it's vastly faster. As I'll mention below, tasks that take more than 20 minutes on my Ollama server, are done in less than 2 minutes with Cerebras.</p>
<h3 id="mcetoc_1jfn5229m2f">Qwen 3 235B Instruct</h3>
<p>I found this model to sit between OSS 120B and the ZAI GLM models. It’s built mainly for coding in popular languages and does a solid job overall.  It feels like a junior developer: you have to spell out every step, or it gets lost.  It outperforms OSS 120B but doesn’t reach the level of the ZAI GLM models.</p>
<h2 id="mcetoc_1jfn568l52i">Lessons Learned</h2>
<p>While continuing to work through <a href="https://nostarch.com/learn-physics-functional-programming">Learn Physics with Functional Programming,</a> I’m already thinking in functional terms about how to structure code. The LLMs make that mindset a necessity: they force me to lay out clear, logical steps toward a goal. The result is cleaner reasoning on my side and more useful, focused responses from the models.</p>
<p>Having a “free” junior developer at hand lets me focus on the tooling and glue scripts I need but can’t write myself. I spend about 15 minutes drafting logical prompts, and the model delivers a working program.</p>
<p>For example, my <a href="https://code.lewman.com/random-configs/file?name=openbsd/autosize.sh&amp;ci=tip">openbsd/autosize.sh</a> script had a bug for a long time where it didn't quite calculate the sizing correctly. I always corrected this bug in my head when running the script. I asked opencode/zai-glm to figure it out. After roughly 25 minutes of iterating, it solved the issue and presented a working script. Why 25 minutes? Because it went down some very odd paths to finding and solving the bug. After reviewing the output, I asked it to write the commit message and then commit it. This <a href="https://code.lewman.com/random-configs/file?name=openbsd/autosize.sh&amp;ci=dcc8e1cad9e9715f">commit</a> is 100% human-in-the-loop but "AI" written and committed. I tested the exact same revision and code with Cerebras AI and the 25 minutes was reduced to roughly 2 minutes.</p>
<p>As for<a href="https://fedoraproject.org/atomic-desktops/silverblue/"> Fedora Silverblue</a>, it just worked. Every update requires a reboot, which gets annoying fast. Even <code>rpm-ostree apply-live</code> didn't work well. I found myself updating just before shutting down to avoid rebooting in the midst of a coding session.</p>
<h2 id="mcetoc_1jfn9n9im2l">TL;DR</h2>
<p>More logical thinking, "cheap" junior developer with the right model. Cerebras is faster than my Ollama machine. </p>
            ]]>
        </content>
    </entry>
    <entry>
        <title>DROP in CA</title>
        <author>
            <name>Andrew</name>
        </author>
        <link href="https://blog.lewman.com/failing-to-drop-in-ca.html"/>
        <id>https://blog.lewman.com/failing-to-drop-in-ca.html</id>
            <category term="privacy services"/>
            <category term="government"/>

        <updated>2026-01-21T23:57:51-08:00</updated>
            <summary type="html">
                <![CDATA[
                    Originally, I wrote this post entitled "Failing to DROP in CA". After&hellip;
                ]]>
            </summary>
        <content type="html">
            <![CDATA[
                <p>Originally, I wrote this post entitled "Failing to DROP in CA". After over a month of waiting and trying, I finally managed to file a DROP request to delete my data from 577 data brokers. The fact that it's this difficult and time consuming is disheartening. The magical incantation on the eighth try (literally 7 failed attempts) seems to have worked. No idea what it was, because it was surely similar to the past seven.</p>
<p>My final thought still stands, we should pass a law that is opt-out by default. Consumers should have to opt-in to any of the data tracking, data recording, data brokering, marketing, etc. The default should be opt-out.  Holding data, especially personally identifying information (PII), should be as toxic as nuclear waste or child abuse material. And breaches should be very punitive, say around $1 million per record per breach, the proceeds of which go into the CA State General Fund. Yes, now I'm making policy. </p>
<p>Without further ado, the original Failing to DROP in CA post:</p>
<hr>
<p>I've now tried multiple ways to use the CA DROP Act to remove my data from data brokers. They've all failed. I'm not a lawyer, this is not legal advice. I'm just trying to exercise my legal rights. <em>sigh</em> nothing can "just work" anymore.</p>
<p>TL:DR: Should you do this as a CA resident?  Yes. Removing data is better than not.</p>
<p>Let's begin, pedantically.</p>
<p>First, load <a href="https://consumer.drop.privacy.ca.gov">https://consumer.drop.privacy.ca.gov</a> where you're forced to accept the terms and conditions of Cloudflare, a third-party commercial service, to even get to the site. Of course, this is automated, unless you block WebGL and websockets (we'll return to this later) and are prompted with an endless stream of CAPTCHA requests and challenges to complete. <em>sigh</em></p>
<p>Ok, load up a clean browser in a virtual machine. Now we get "Verified" automatically, which automatically means I've accepted the T&amp;C apparently by loading the page?  I can't read them, etc, because it all happens in a split second, so did I really agree? I have no choice if I want to get to the DROP site.</p>
<p>Once at the DROP page, you're forced to scroll through the entire Terms of Service. I do actually read these and put them through <a href="https://tosdr.org/en">TOS:DR</a> usually. In the first section is "Use of DROP", the first paragraph:</p>
<blockquote>
<p>By submitting a deletion request through DROP, you consent to disclosure of your personal information to data brokers for purposes of processing your deletion request pursuant to Civil Code section 1798.99.80 et seq. unless or until you cancel your deletion request. Additionally, you acknowledge that data brokers receiving your deletion request will delete any non-exempt "personal information," as defined in Civil Code section 1798.140(v), which pertains to you and was collected from third parties or from you in a non-"first party" capacity (i.e., through an interaction where you did not intend or expect to interact with the data broker).</p>
</blockquote>
<p>Ok, what are 1798.99.80 and 1798.1.40(v)? They aren't linked so, we'll have to go search for them. Of course, there a thousand private companies that will sell you access to the laws to which you're beholden. However, finding the actual ca.gov site that hosts the laws is at <a href="https://leginfo.legislature.ca.gov/faces/codes.xhtml">https://leginfo.legislature.ca.gov/faces/codes.xhtml</a>.   To start, we agree to <a href="https://leginfo.legislature.ca.gov/faces/codes_displaySection.xhtml?sectionNum=1798.99.80.&amp;lawCode=CIV">1798.99.80</a> which basically defines what is a data broker. The next definition is<a href="https://leginfo.legislature.ca.gov/faces/codes_displaySection.xhtml?sectionNum=1798.140.&amp;lawCode=CIV"> 1798.1.40(v)</a> which defines personal information and exceptions to personal information. Definition v(1) is a long definition which includes what you normally think of as "personal information". As well as some items which you probably don't think of as personal info and then a list of what attributes are exempted from the "personal information" definition. Data Brokers can keep everything in v(1) 2(A), 2(B), and (3) as sub definitions under the v(1) definition of "personal information". Confused yet? Probably by design. I find (3) interesting, because it states:</p>
<blockquote>
<p>(3) “Personal information” does not include consumer information that is deidentified or aggregate consumer information.</p>
</blockquote>
<p>There is no such thing as "deidentified" information. All information in aggregate can be paired with other information in aggregate and start to build profiles. This is what k-anonymity and differential privacy techniques are designed to prevent. However, current research says k-anonymity doesn't work and differential privacy techniques are a complex matter for the talented data scientist to understand, never mind the average educated consumer.</p>
<p>Next we get to the paragraphs about verifying California "residency". Of course, this mentions a law code but doesn't link to it. The code is:</p>
<blockquote>
<p> section 17014 of Title 18 of the California Code of Regulations as that section read on September 1, 2017</p>
</blockquote>
<p>Interesting specificity there, why 01 September 2017?  And where can I find this specific version?  I couldn't find it, only the <a href="https://www.law.cornell.edu/regulations/california/18-CCR-17014">general regulation</a>. Assuming we are CA residents by that definition, let's move on. </p>
<p>We get to the section entitled, "Third-Party Links", which I found comical.</p>
<blockquote>
<p>DROP may contain links to other websites and access to content and services of third parties, including verification services provided by our contracted vendors (Third-Party Content). We exercise no control over such Third-Party Content, and the Third-Party Content is governed by the respective third party’s website terms and conditions. We are not responsible for Third-Party Content’s accuracy, completeness, or legality. By using DROP, you acknowledge and agree that your use of any Third-Party Content is at your own risk. We shall not be liable for any damages arising from your reliance on or use of such Third-Party Content.</p>
</blockquote>
<p>I'll highlight one sentence there, "By using DROP, you acknowledge and agree that your use of any Third-Party Content is at your own risk." That's right, you have to use the CA DROP site, with all the included third party content, links, and forced services, but it's at your own risk. Consumer beware.</p>
<h1>Technology Break</h1>
<p>Let's open up developer tools and see what other third parties stalking us while we read the ToS. Here's a screenshot for what I see just loading up the site:</p>
<figure class="post__image post__image--wide"><img loading="lazy" src="https://blog.lewman.com/media/posts/947/Screenshot_2026-01-22_00-23-53.png" alt="developer tool screenshot" width="1854" height="186">
<figcaption>websockets and banned scripts galore</figcaption>
</figure>
<p>Here are the details from the image:</p>
<p><code>VM7 m=el_conf:5 Uncaught TypeError: _.v is not a function<br>www.googletagmanager.com/gtag/js?id=G-ZLS9WVTG9N:1  Failed to load resource: net::ERR_BLOCKED_BY_CLIENT<br>VM26 inject-root-bundle.js:1 RSS_Basic_Detect.js: Expected contentType string<br>Jn @ VM26 inject-root-bundle.js:1<br>blazor.web.js:1 </code></p>
<p><code>[2026-01-22T07:39:54.557Z] Information: Normalizing '/_blazor' to 'https://consumer.drop.privacy.ca.gov/_blazor'.<br>blazor.web.js:1 </code></p>
<p><code>[2026-01-22T07:39:54.719Z] Information: WebSocket connected to wss://sigr-drop-prod-003.service.signalr.net/client/?hub=componenthub&amp;asrs.op=%2F_blazor&amp;negotiateVersion=1&amp;asrs_request_id=<br>blazor.web.js:1 </code></p>
<p><code>[2026-01-22T08:07:31.229Z] Information: Connection disconnected.<br>blazor.web.js:1 </code></p>
<p><code>[2026-01-22T08:07:31.231Z] Information: Normalizing '/_blazor' to 'https://consumer.drop.privacy.ca.gov/_blazor'.<br>blazor.web.js:1 </code></p>
<p><code>[2026-01-22T08:07:31.400Z] Information: WebSocket connected to wss://sigr-drop-prod-003.service.signalr.net/client/?hub=componenthub&amp;asrs.op=%2F_blazor&amp;negotiateVersion=1&amp;asrs_request_id=<br></code></p>
<p>For a future post, I'll explain my layered approach to ad-blocking, anti-phishing, etc. For now, google tag manger is blocked. What is this websocket connection? This is the wss:// link. Why does CA DROP need a websocket realtime connection to the site? And who is signalr.net? It's a library included for ASP.net websites to send notifications to clients. You can learn more at <a href="https://en.wikipedia.org/wiki/SignalR">https://en.wikipedia.org/wiki/SignalR</a>. Ok, two third parties so far. </p>
<p>Even better, my browser blocked 9 ads and/or 9 trackers according to the ad blocker. Eight of these are google tag manager, one is google translate. Still only two third party sites, but one of them is a massive data vampire. Great &lt;/sarcasm&gt;</p>
<h1>Back to the Process</h1>
<p>So we get through it all and we press the  "I accept" button. We're taken to the "Verify you're a California resident" page. There are two buttons "Use  personal information" and "Use Login.gov". Let's pick one.</p>
<p>When *I* click on "Use personal information", the page turns gray and nothing happens.  In digging through developer tools again, I find there's supposed to be a modal overlay that says,</p>
<blockquote>
<p>The personal information you enter here will only be used to help determine you are a California resident. The information will not be shared or stored after verification.</p>
</blockquote>
<p>However, I see nothing. There's apparently two buttons on this overlay. The overlay doesn't work because it's served up by a google tag manager url. Ugh. I have to completely disable the adblocker to get the modal overlay to even show up.  I do this and now load "Use personal information for identity and residency verification" web page. Which is a form asking for some personal information so they can verify I'm a CA resident. I enter my information and use an email for the code I'm supposed to receive. <strong>The email never arrives. </strong></p>
<p>Start over, go through the whole process and enter a phone number. I receive the verification code, enter it and </p>
<blockquote>
<h2 class="error-message">We couldn't verify you're a California<br>resident.</h2>
</blockquote>
<p>This is the same information on my driver's license, my mailing address, my FTB information, and well, everything. If I don't pay taxes, you'll be guaranteed the State of CA will verify I'm a CA resident and hunt me down. However, none of this is good enough for CA DROP. <em>sigh</em>. </p>
<p>If I click the "try another way" button, it resets my session and I start over. If I click the residency review assistance link, it takes me to a form to fill out to request a review. I fill out the form and get a nice note:</p>
<blockquote>
<p>Our agency will do our best to reach out to you by email within two weeks.</p>
</blockquote>
<p><em>Two weeks pass</em>: I never hear from CA DROP via email. </p>
<h1>The Other Way</h1>
<p>There were two buttons on the page after "I accept" was clicked. Let's try Login.gov now.</p>
<p>After logging into my account, I'm told to either click on a link on a mobile phone or print a QR Code to take to the Post Office for them to verify I am who I say.</p>
<p>Why do I have to upload a driver's license via a mobile browser only?  My login.gov account was good enough for the IRS to hunt me down, but not good enough for CA residency? <em>sigh</em>. I will <strong>never</strong> upload an ID to the Internet, especially when it's hosted by some third party service who promises not to store or lose the image. We've all seen how well that goes for everyone involved--spoiler, they all store the data forever in some insecure manner and then are just <em>SHOCKED</em> when the copies of IDs are leaked everywhere. Until I can replace my face, or replace my "government ID" with ease, I don't upload my identification documents anywhere. </p>
<p>So here we are, I can't use CA DROP as it is now. I'm guessing this is the desired plan. Maybe I should lobby for a law to enforce opt-out by default for everything online. </p>
<figure class="post__image post__image--wide"><img loading="lazy"  src="https://blog.lewman.com/media/posts/947/ca62043061e64a9567c70c8da77a434a6958c56a9a43f03b6d24594074c3cc3a.avif" alt="I wake up. I am spied on in new ways." width="508" height="500"></figure>
            ]]>
        </content>
    </entry>
    <entry>
        <title>Confidential LLM</title>
        <author>
            <name>Andrew</name>
        </author>
        <link href="https://blog.lewman.com/confidential-llm.html"/>
        <id>https://blog.lewman.com/confidential-llm.html</id>

        <updated>2026-01-05T18:06:27-08:00</updated>
            <summary type="html">
                <![CDATA[
                    About 18 months ago, I took a contract to build an "offline&hellip;
                ]]>
            </summary>
        <content type="html">
            <![CDATA[
                <p>About 18 months ago, I took a contract to build an "offline end-to-end encrypted LLM" for a client. After some research, I ended up building a system around the AMD EPYC CPUs and lots of very fast RAM. I didn't have access to fancy GPUs with secure enclaves. This system is going to run in pure CPU, but has to perform as close to a GPU. What does performance mean?  In this case, it meant fidelity of results. The content of the results should be the same, whether run on a GPU or the E2EE LLM. The speed of the results will be different, obviously. </p>
<p>Why AMD EPYC?  Because they have hardware memory encryption, very fast memory bandwidth, and SEV-SNP for confidential computing. Tie in encrypted filesystems reliant on the TPM and a hardware key. From a "secure boot" setup, through answering a query, the entire data flow was end-to-end encrypted. If at any point in time the server was seized, compromised, or other security calamity happens, the data is encrypted and safe. If something failed in the "secure boot" or anywhere along the authentication/encryption chain, then the validity/authentication is broken and the system will continue, but will not guarantee any results. The system was audited, security reviewed, and the customer still uses it today. </p>
<p>However, while the customer tied it into their larger authentication system, I wanted to build something that was end-to-end encrypted <em>and</em> anonymous. Privacy is usurped by endless legal agreements, "what we collect about you" verbiage, and "how to opt-out" paragraphs (an argument for another time: <em>why not ask us to opt-in instead of opt-out?</em>). What if there were no personally identifying information? No email login/password combination? What if the system was entirely ephemeral, has zero logs, and had only temporary ram filesystems?</p>
<p>Taking an idea from Mullvad and BIP39 Mnemonics, could we build a system that allows for user-controlled authentication that is anonymous to the provider? I want it to work without a phone, without requiring passkeys, or other extra devices. A secure browser (Brave, Mullvad, Tor Browser, Firefox with Arkenfox, etc) should be all you need. A progressive web app should work just as well. I understand the world loves mobile phones, but the system shouldn't require one.</p>
<p>I have a test system running based on an AMD EPYC 9135 16-Core Processor. It's not impossibly fast, but it works and I've been using it for a few weeks without issue. There's a basic slider that lets the user choose between "confidential, secure, and private":</p>
<ul>
<li>Confidential is "fully within the Trusted Execution Environment (TEE)", meaning entirely on the CPU. Unless someone has access to the fancy GPUs with TEEs.</li>
<li>Secure is within the TEE except the GPU is exposed and queries are sent across the local PCIe bus to the GPU, executed, and sent back to the TEE to return the results. This requires the user trusts the local PCIe bus and the GPU in the system.</li>
<li>The final option, private, allows for third-party APIs carried out under a proxy account with TLS-wrapped queries. I could extend this to cloud providers using their TEE offerings. </li>
</ul>
<p>I'm thinking of how to turn this into a service, in the crowded space of "AI LLM hosting" and/or a "confidential LLM in a box" that you can buy and self-host. Work continues. I'm happy to hear from you if you’re interested—please use <a href="https://web.lewman.com/contact.html">my contact page</a>.</p>
            ]]>
        </content>
    </entry>
    <entry>
        <title>What I&#x27;m Reading This Month</title>
        <author>
            <name>Andrew</name>
        </author>
        <link href="https://blog.lewman.com/what-im-reading-2.html"/>
        <id>https://blog.lewman.com/what-im-reading-2.html</id>

        <updated>2025-12-16T23:48:29-08:00</updated>
            <summary type="html">
                <![CDATA[
                    I don't have a "microblog" or "federated social media" account because I&hellip;
                ]]>
            </summary>
        <content type="html">
            <![CDATA[
                <p>I don't have a "microblog" or "federated social media" account because I find the ease of posting distracting. I could spend all my free time whittled away in trivial conversations. I was thinking about this when the three millionth person suggested I join Instagram. I don't understand the IG. If you do, and find it useful, great. I refuse to join anything related to Meta/Facebook/Whatever-they're-called-this-year. It's all a big data vacuum. I can burn time on xmpp, irc, matrix, or delta chat just fine; no need for big tech companies to mediate the experience. </p>
<p>Instead, I read longer form articles on purpose. All that is a preface to a few links:</p>
<ul>
<li>
<p>How We Lost Communication to Entertainment, <a href="https://ploum.net/2025-12-15-communication-entertainment.html">https://ploum.net/2025-12-15-communication-entertainment.html</a></p>
</li>
<li>This is not the future, <a href="https://blog.mathieui.net/this-is-not-the-future.html">https://blog.mathieui.net/this-is-not-the-future.html</a></li>
<li>You're overspending because you lack values, <a href="https://www.sherryning.com/p/youre-overspending-because-you-lack-values">https://www.sherryning.com/p/youre-overspending-because-you-lack-values</a></li>
<li>Cultivating Innovation in a Research Lab, <a href="https://cacm.acm.org/opinion/cultivating-innovation-in-a-research-lab/">https://cacm.acm.org/opinion/cultivating-innovation-in-a-research-lab/</a></li>
<li>Reinventing AI: Is it Time for a New Paradigm? <a href="https://cacm.acm.org/opinion/reinventing-ai-is-it-the-time-for-a-new-paradigm/">https://cacm.acm.org/opinion/reinventing-ai-is-it-the-time-for-a-new-paradigm/</a></li>
<li>Tech Workers vs Enshittification, <a href="https://cacm.acm.org/opinion/tech-workers-versus-enshittification/">https://cacm.acm.org/opinion/tech-workers-versus-enshittification/</a></li>
<li>Quantum Computing, <a href="https://nostarch.com/quantum-computing">https://nostarch.com/quantum-computing</a>. Every book on quantum computing spends the first twenty-five percent of the book speed-running undergraduate and graduate math classes; calculus, linear equations, etc. This book is no different. Maybe after reading a few of these books, I'm finally remembering the math lessons.</li>
<li>Learn Physics with Functional Programming, <a href="https://nostarch.com/learn-physics-functional-programming">https://nostarch.com/learn-physics-functional-programming</a>. Literally reading this for fun. I'm re-learning Haskell as a side benefit. </li>
<li>Goliath's Curse, <a href="https://en.wikipedia.org/wiki/Goliath%27s_Curse">https://en.wikipedia.org/wiki/Goliath%27s_Curse</a>. </li>
<li>Making It So, <a href="https://patrickstewartbook.com/">https://patrickstewartbook.com/</a>.  This is a cheat as I started reading it over the summer, but then come back to it every so often.</li>
<li>Make Your Own Neural Network, <a href="https://bookshop.org/p/books/make-your-own-neural-network-tariq-rashid/36f95415033beace?ean=9781530826605&amp;next=t">https://bookshop.org/p/books/make-your-own-neural-network-tariq-rashid/36f95415033beace</a>.  We have no end of power in our existing devices, especially if yours includes an NPU. This is focused on python, but the principles work with any programming language. I use julialang. I may start using Haskell as I relearn it. </li>
</ul>
            ]]>
        </content>
    </entry>
</feed>